How to Run Multiple Claude Code Sessions in the Same Repo Without Conflicts
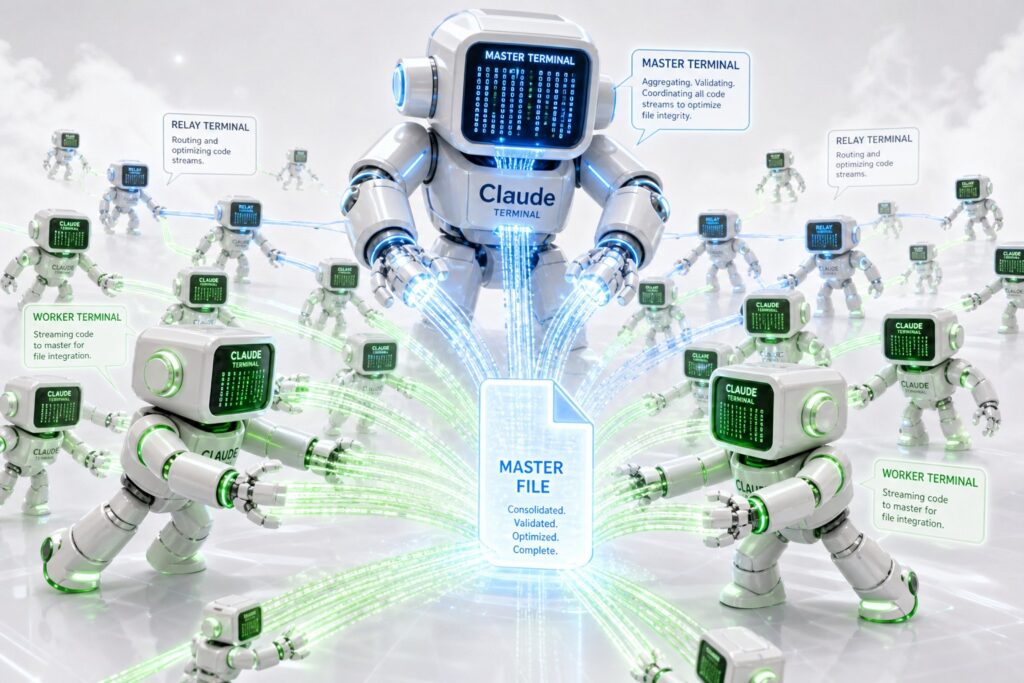
Give each Claude Code session its own git worktree and its own branch, so every session edits an isolated working directory while sharing one repository history. Assign each session a distinct set of files, keep tasks small, commit often, and merge through pull requests so git resolves conflicts before anything reaches main.
For most of my career in algorithmic trading, the person most likely to break my code was somebody else. Trading systems change constantly, and the pain was rarely a single bad change; it was the merge, where two engineers altered the same strategy or order handling logic in different branches, both sets of tests passed in isolation, and the combined result behaved in a way neither of them intended. The defences the industry relies on for this are familiar: code owners, branch protection, review gates, merge queues and the long, slightly tribal arguments about who was allowed to touch which file. All of them assume that the conflict is between people, that the people are on different machines, and that git sits in the middle as the referee.
That world has quietly inverted for me. Today the most likely source of a conflict in my repositories is me, or more precisely the several Claude Code sessions I have running at once, each of them confident, fast and entirely unaware of the others. When those sessions share one checkout there is no pull request between them, no branch, no reviewer and no merge queue, and I still need some agreement on who is working on what, even though every participant is running under my own user account.
Separate git worktrees are the simplest way to isolate parallel Claude Code sessions, and they are the approach Anthropic’s documentation describes. For small, closely related tasks, though, I sometimes keep several sessions in one checkout, because the merge overhead of separate worktrees outweighs the work itself. After four incidents involving uncommitted work, I built the Session Coordinator in Claude Burst to assign one commit owner per file, block common destructive operations and record dirty deployments. It reduces the risks of a shared checkout, but it does not provide worktree isolation, and this post tries to be precise about where that line sits.
I should also be clear about the setting. This is me working on my own projects, by myself, on my own laptop, where I deploy directly from my working tree with a script. Large corporates largely avoid the most dangerous version of this problem because nothing reaches production except through a CI/CD pipeline that builds from a commit, so uncommitted work on a laptop cannot ship. That protection only covers the last step, however. Even behind a proper pipeline, an engineer running several sessions in one checkout can still have sessions overwriting each other’s files, sweeping each other’s half finished changes into the wrong commit, and stashing or resetting the working tree out from under each other, all before anything is pushed. The pipeline faithfully builds whatever was committed; it cannot know that the commit itself was a collision between two sessions.
1. The Incident That Forced the Issue
On 1 October 2026 one Claude Code session ran scripts/deploy.sh for Claude Burst. The script did exactly what it was written to do: it built the working tree and shipped it. The working tree also held another session’s uncommitted edits, which had survived a couple of context compactions and restarts, and those edits went to production along with everything else. The tests happened to pass, so nothing visibly broke, but production was now running code that existed in no commit, and the session that had written those changes had already ended, so there was nobody left to tell. The same pattern had already hit my WordPress plugins three times in August. Parallel sessions rarely fail by crashing into each other in some obvious way; they fail quietly, by sweeping up each other’s work and carrying it somewhere it was never meant to go.
2. How Sessions Trip Over Each Other
The failure modes are not exotic, and they map closely onto the mistakes people make in a shared repository, except that an agent makes them at machine speed and without social hesitation. One session uses a whole file Write and destroys another session’s uncommitted change to the same file. One runs git add -A or git commit -a and commits another session’s half finished work under its own message. One runs git stash, git reset --hard, git checkout -- or switches branch under a session that is midway through something. One deploys a working tree containing someone else’s uncommitted work. And one ends with changes still uncommitted, at which point nobody owns that work any more.
3. What the Coordinator Is, and What It Is Not
It is worth stating the guarantees before the mechanism, because a coordination layer that overstates them is more dangerous than none at all. The coordinator reduces accidental collisions while it is operating; it does not guarantee isolation. It works by intercepting Claude Code’s tool calls through hooks, so it only sees what passes through those hooks, and it deliberately fails open: if its state lock is busy for more than 3 seconds, its state file is corrupt or any other error occurs, the tool call goes ahead exactly as though coordination were switched off. I chose availability over strictness on purpose, because a coordinator that can freeze every session on the machine is worse than the problem it solves, but it means words like “enforced” in this post always carry the qualifier “while the coordinator is working”.
Those failures are not hidden. Each one is logged as a hook error and opens an Issue on the Claude Burst dashboard, and the Session coordination menu item shows a red dot while any Issue is open. They are not, however, pushed into the affected session or raised as a system notification, so a failure is visible only if I look at the dashboard. Section 12 explains the counters and the most common error.
I considered and rejected the alternatives. Separate worktrees remain the right tool for large, independent work, but they add merge overhead to the small, closely related tasks I run in one checkout. Classic file locking fails because AI sessions hold files for minutes or hours, so waiting wastes time and invites deadlock. Automatic merging is hard to do well, and a wrong merge hides the problem rather than surfacing it. Having the coordinator commit on a session’s behalf would mean commits made by something that had not read the diff. And simply instructing the model in its prompt is exactly what had already failed four times.
4. The Model: One Commit Owner Per File, Nobody Waits
The coordinator’s central rule is that each file has a single commit owner, which the tool calls its master, with any number of coordinated contributors. The first session to Edit or Write a file becomes its master, and the master is the only session allowed to commit that file. Other sessions can still edit it; they become contributors and are told not to commit it themselves. Ownership decides who commits a file, not who wrote each part of it: when the master commits a contributor’s change alongside its own, git records a single author for the combined result, and the coordinator does not track hunk level authorship.
The second rule is that coordination never makes a session stop and wait for another. Instead of locking files, it speeds up commits. When a contributor edits a file, the master receives a PRIORITY message at its very next tool call telling it to commit that file now, before its next step, staged by name, with “WIP:” in the message if its own part is unfinished, and it is nudged again if it has not done so within 10 minutes. A small early commit costs almost nothing, while a session sitting idle waiting for a lock burns time and context.
Allowing contributors to edit without waiting relies on how Claude Code’s Edit tool behaves. Edit replaces an exact piece of text and refuses if the file has changed since the session last read it, so when two sessions edit the same file the second usually fails and rereads rather than overwriting. That makes conflicting edits far more likely to be detected than missed, but it is not an atomic guarantee across independent processes. The coordinator serialises its own decisions under a lock, as described below, but that lock is released before the file operation itself happens, so it does not cover the write. I have not yet run a test of two sessions editing the same file at genuinely the same instant, and until I do, the honest claim is that conflicting edits are usually detected, not that they cannot be lost.
The decisions themselves are serialised through one small JSON state file at ~/.config/claude-burst/coord/state.json. Every hook reads it, decides and writes it back while holding an exclusive flock, so decisions are applied one at a time and every session sees the result of every earlier decision. There is no distributed consensus algorithm here, because all the sessions run on one machine. Liveness is taken from the later of a session’s last hook call and the modification time of its transcript file, which Claude Code appends to on every turn, so there are no heartbeats and no daemon. Each session has an inbox in the same file, delivered at its next tool call or prompt through the hook’s additionalContext, and every session is briefed at start with the rules and with which other sessions are active, where, and which files they master.
5. The Hooks
The coordinator is built from seven Claude Code hooks, installed into ~/.claude/settings.json from the Claude Burst dashboard, so every Claude Code session on the Mac takes part without being configured individually; the lifecycle they use is the one in Anthropic’s hooks reference. SessionStart registers and briefs the session. PreToolUse on Edit and Write claims or shares the file, takes it over from an idle master where the rules allow, and refuses a whole file Write over someone else’s uncommitted work. PreToolUse on Bash refuses sweeping git commands, refuses staging files the session has contributed to but does not master, and refuses deploy or install scripts while other sessions have uncommitted work. PostToolUse releases files after a git commit and delivers PRIORITY messages and nudges, as does UserPromptSubmit. Stop holds a session once at the end of a turn until it commits what it masters. SubagentStop records that a background agent has finished. SessionEnd hands the session’s files on.
sequenceDiagram
    autonumber
    participant A as Session A (master of x.go)
    participant C as Coordinator (hooks + state.json)
    participant B as Session B
    A->>C: Edit x.go (PreToolUse)
    C-->>A: First editor, you are master
    B->>C: Edit x.go (PreToolUse)
    C-->>B: Allowed. Shared file, do not commit it, A will
    C->>C: Queue PRIORITY message for A
    A->>C: Next tool call (PostToolUse)
    C-->>A: PRIORITY: commit x.go now, before your next step (WIP: if unfinished)
    A->>A: git add x.go and git commit
    C->>C: x.go clean, released
6. Handing Files On
At the end of each turn, if a session masters files git reports as uncommitted, the Stop hook returns {"decision":"block"} once, telling it to commit those files by name, locally and never pushed, with “WIP:” if unfinished. A second Stop in the same turn is let go and logged as an Issue, so a commit that genuinely cannot be made, for example because a pre-commit hook fails, never traps the session in a loop. The result is more commits than I would make by hand, many of them WIP, which I accept because a WIP commit is visible, attributable and revertable while an uncommitted edit in a shared tree is none of those.
An idle master keeps its files until someone needs one. When another session edits a file whose master has been idle for longer than the Master idle setting, 15 minutes by default, or has ended, that session becomes master on the spot and is told to keep any uncommitted changes it inherits; the old master is told it has lost the file. A session can ask a busy master for a file with claude-burst coord take <path> --session <id>, and its edits still go through as contributions in the meantime. When a master ends, each file goes to whoever asked for it, otherwise to whoever most recently changed it, otherwise it is freed, and a session with no sign of life for 2 hours counts as gone.
7. The Shared Git Index: The Gap That Remains
Sessions sharing a checkout also share one git index, and this is the most important limit of the current design. The coordinator inspects the command a session is about to run; it does not yet inspect what is already staged. Consider Session A staging api.go, which it masters, and then pausing. Session B stages README.md, which it masters, and runs an ordinary git commit -m "docs". Nothing in that command is refused, because B named no file it is barred from and used no sweeping flag, yet git commits everything in the index, so B’s commit contains A’s api.go under B’s message.
What is checked today is narrower than that example requires. git add -A, git add ., git add -u and git commit -a are refused while another session has recorded work in the repository. Staging a file the session has contributed to but does not master is refused, based on the file appearing in the command. Staging a file another session masters but this session never edited is not refused, and a plain git commit is never checked against the index. The fix is straightforward in principle: before any commit, compare git diff --cached --name-only with the ownership records and refuse if the index holds files another session masters. Until that check exists, the commit owner rule reduces sweeping commits but does not prevent this one.
8. Deploying Without Waiting
When a session runs a deploy or install script while another session has uncommitted work in that repository, the deploy is refused before anything runs. The coordinator finds the repository from the current directory, from any cd targets in the command and from the script’s own path, and it distinguishes reading a script with cat or grep from running it. The deploying session is not left waiting: the coordinator sends a PRIORITY message to each master holding uncommitted work telling it to commit now, and tells the deployer to carry on with other work and retry once those files are clean. Only on my explicit say so can uncommitted work be shipped, using SHIP_UNCOMMITTED=1.
flowchart TD
    D["Session B runs a deploy script"] --> Q{"Other sessions have uncommitted work in this repo?"}
    Q -- No --> RUN["Deploy runs"]
    Q -- Yes --> R["Deploy refused, nothing run"]
    R --> M["Coordinator sends PRIORITY to each master: commit now, B needs to deploy"]
    R --> B2["B told: carry on with other work, retry when files are clean"]
    M --> CM["Masters commit, WIP: if unfinished"]
    CM --> RETRY["B retries the deploy"]
    B2 --> RETRY
    RETRY --> RUN
    Q -- "deploy.sh --only-committed" --> HEAD["Builds a worktree of HEAD and runs"]
    classDef ok fill:#e6f4ea,stroke:#2e7d32
    classDef stop fill:#fdecea,stroke:#c62828
    classDef act fill:#e8f0fe,stroke:#1a56db
    class RUN,HEAD ok
    class R stop
    class M,CM,B2,RETRY act
The deploy scripts add a second, independent layer that records rather than refuses, because a script cannot tell whose uncommitted changes are whose, and a guard that refused every dirty deploy would turn its override into a habit. Claude Burst’s deploy.sh and install.sh list every uncommitted file they ship and keep a patch and a tarball of untracked files in ~/.config/claude-burst/shipped-uncommitted/, retaining the newest 50. For the WordPress plugins, deploy-wordpress.sh writes a manifest beside every archived zip recording the commit the build was based on and every file that differed from it.
deploy.sh --only-committed builds from a throwaway worktree of HEAD and is let straight through. That means it builds from the selected commit rather than the shared dirty checkout, and it prints that commit’s short hash as it starts. It does not, on its own, guarantee that the deployed artifact exactly matches the commit: dependencies, generated files, environment inputs and packaging can still differ, and it does not yet record the resolved commit SHA and an artifact checksum together. Recording both is the next step if I want to be able to prove what production is running.
9. The Subagent Problem
Claude Code sessions launch subagents through the Agent tool, often in the background and often in their own worktree. A subagent’s hook calls carry its parent session’s id, so the coordinator originally saw the agent’s edits as the parent’s own, and when the parent finished its turn while the agent was still working, the Stop hook told the parent to commit files the agent was halfway through writing. The parent rightly refused. The fix uses the agent_id that hook input carries inside a subagent: the coordinator records which subagent last edited each file, tracks each session’s running subagents from their first tool call until SubagentStop, treats one silent for 2 hours as finished, and leaves a running subagent’s files out of the end of turn check until the agent is done.
flowchart TD
    S["Session turn ends: Stop hook"] --> F["For each file the session masters"]
    F --> AG{"Last edited by a subagent that is still running?"}
    AG -- Yes --> SKIP["Leave it: the agent is still working"]
    AG -- No --> DIRTY{"Uncommitted changes?"}
    DIRTY -- No --> OK["Nothing to do"]
    DIRTY -- Yes --> HOLD{"Already held once this turn?"}
    HOLD -- No --> ASK["Hold the session: commit these now, locally, WIP: if unfinished"]
    HOLD -- Yes --> LOG["Let it stop, log 'stopped with uncommitted' as an Issue"]
    SA["SubagentStop hook"] --> GONE["Remove agent from running list: its files become the session's to commit"]
    classDef ok fill:#e6f4ea,stroke:#2e7d32
    classDef warn fill:#fff4e5,stroke:#b26a00
    classDef act fill:#e8f0fe,stroke:#1a56db
    class OK,SKIP ok
    class LOG warn
    class ASK,GONE act
10. Every Timeout in the System
| Timer | Default | What happens |
|---|---|---|
| Master idle | 15 min (setting) | another session’s edit takes the file over |
| Nudge | 10 min (setting) | a master that has not committed a contributor’s change is reminded again |
| Session dead | 2 h | with no sign of life, the session is treated as gone and its files are handed on |
| Subagent silent | 2 h | a subagent with no activity counts as finished |
| State lock wait | 3 s | the tool call proceeds uncoordinated (fail open) and a hook error is logged |
| Stop hold | once per turn | the second Stop in the same turn is let go and logged as an Issue |
Deploy lock (deploy.sh) | 10 min | a second deploy waits for the first; a dead holder’s lock is taken over |
The deploy lock is the one place where something deliberately waits, because two concurrent deploys of the same thing are a different class of problem from two sessions editing files.
11. Trying It
Coordination is off by default. After installing Claude Burst from the repository, a first run looks like this:
- Open the Claude Burst dashboard, find Session coordination under Leading Edge and switch it on. This installs the coordinator’s hooks into
~/.claude/settings.json; switching it off removes only those hooks. - Start two Claude Code sessions in the same repository and give each a small task that touches the same file. Each is briefed about the other when it starts.
- Run
claude-burst coord statusto see which session masters the file and which is contributing, or watch the same tables on the dashboard. - Let the master commit when it receives its PRIORITY message, and confirm the file is released afterwards.
- Deploy from the committed state, for Claude Burst itself with
scripts/deploy.sh --only-committed, and check the “Is it working?” panel for the counts and any Issues.
12. Seeing Whether It Works
The dashboard’s “Is it working?” panel counts the coordinator’s own log over Today, 7 days or 14 days, with an all time total on each tile and a per day table underneath.
| Metric | What it counts | How to read it |
|---|---|---|
| Coordinated | every time two sessions met over the same file or repository and coordination stepped in: the sum of shared edits, blocked actions, files taken over or handed on, and files asked for | zero means no two sessions have touched the same work yet, not that the coordinator is broken |
| Shared edits | a session edited a file another session masters | the edit went through and the master was asked to commit it |
| Blocked | a whole file Write over someone else’s uncommitted work, a sweeping git add -A or git commit -a, staging a file the session contributed to but does not master, or a deploy over others’ uncommitted work | each one is a collision that would otherwise have happened silently |
| Taken over or handed on | a file moved to a new master because its master was idle, ended, or was asked for it | ownership moving without anyone waiting |
| Asked to commit | a turn ended with mastered files uncommitted, so the Stop hook held the session once | how often the commit before you stop rule had to intervene |
| Stopped uncommitted | a session ended its turn anyway after being asked | the rule failing to get a commit; each one opens an Issue |
| Hook errors | a hook could not complete, so the tool call went ahead uncoordinated | the fail open path being used; each one opens an Issue |
| Released after commit | files freed because they were committed | the normal end of a file’s life in the coordinator |
The ratio that matters most is Asked to commit against Stopped uncommitted. If every session that is asked to commit then stops anyway, the hold is not producing commits, and safe handover depends entirely on the next master noticing the changes it inherits.
The hook errors deserve their own explanation, because on a busy day they are the most visible red number on the page. Almost all of them read state lock: resource temporarily unavailable, in either the pre tool or post tool hook. That means the exclusive flock on state.json was still held by another hook when this hook’s 3 second wait ran out, so the hook logged the error and let the tool call through uncoordinated. A pre tool error means an edit or command was not checked; a post tool error means a commit may not have released its files or a PRIORITY message may arrive one call late. A few of these during bursts of parallel activity is expected, while a steady stream means the hooks hold the lock too long and the hook path needs to become cheaper.
The Issues list holds hook errors and sessions that stopped with uncommitted work; the latter are marked resolved automatically once each file is committed or handed on. Because sessions named after their folder share a window title, each session is shown alongside the latest request of five words or more typed into it, and scratchpad and temp directory files are not tracked at all.
13. What It Cannot Do
Several limits follow from the design, and I would rather list them plainly than have someone discover them in production. The shared git index is not checked before a plain git commit, as section 7 describes. Edit conflicts are usually detected, but the coordinator’s lock does not cover the file write itself, and simultaneous edits have not been tested. Edits made through shell commands, such as sed or a formatter run from Bash, never pass through the Edit and Write hooks; sessions are told not to edit that way, and a file already dirty on its first recorded edit triggers a warning, but neither is a guarantee. Sessions sharing a working tree still see each other’s uncommitted changes, so one session’s test run can be affected by another’s work in progress. Every check fails open, so a busy lock or a broken state file means uncoordinated tool calls, visible on the dashboard rather than in the session. And building from HEAD controls the source inputs to a deploy, not every input to the artifact. For large parallel work, separate worktrees remain the better tool.
14. How It Is Tested
The tests fall into two kinds, and they should not be confused. go test ./internal/coord drives the hooks with simulated sessions against a fake clock and a real git repository, covering two sessions writing a sentence one word at a time, takeover from an idle master, Write refusal, deploy refusal, the Stop hold, subagents and the commit first PRIORITY message. It also includes a lock contention test in which ten post tool hooks run concurrently and must neither give up nor hold the lock for more than a second. The suite is mutation checked, in that switching off each feature makes its tests fail. scripts/coord-live-test.sh then runs two real Claude Code sessions on Haiku, about eleven requests, in a throwaway repository with the hooks passed through --settings, checking that every word lands, nobody waits, the first session becomes master and the master’s commit releases the file.
The live test has the sessions take turns, so it exercises the real hooks against the real tool but is not a concurrent stress test. There is not yet a test of two sessions editing the same file at the same instant, nor of the shared index case in section 7. Everything described here refers to the code as of commit f891bdf.
15. Closing Thoughts
The process we built to stop people on different machines from damaging each other’s work assumed participants who were slow, few and capable of embarrassment. Parallel AI sessions in one checkout break those assumptions, so some of the controls have to move to the tool boundary itself. The approach I ended up with is one commit owner per file, nobody waits, whoever holds work someone else needs commits it now, and every gate fails open with the failure recorded where I can see it. It makes a shared checkout considerably safer than it was, but it is a way of reducing collisions, not a substitute for isolation, and if your parallel work is large or independent, use worktrees.
The code is at github.com/andrewbakercloudscale/claude-burst.