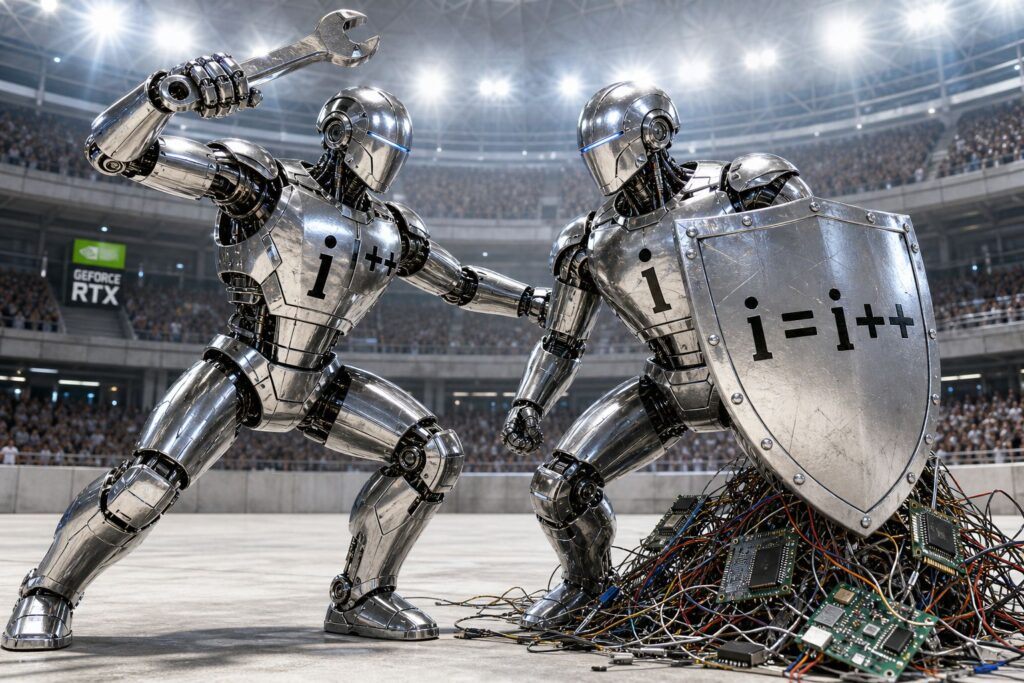
The Software Engineering Interview Question Hiding Inside i = i++
There is a small interview question I like because it starts with something that looks like a typo and ends up taking you through language semantics, integer promotion, the Java Memory Model, x86 versus ARM, store buffers and finally how to write a counter that actually works. It is a great question precisely because most candidates answer the first part confidently and wrongly, and then the follow up questions show you whether they really understand what the JVM and the CPU do with a single line of code. I have split this post in two, so you can work through the questions on your own before reading the answers.
1. The Questions
Here is the code, with i declared as a field at class scope, because nothing else in the question makes sense if it is a local variable:
import static org.junit.jupiter.api.Assertions.assertEquals;

public class Foo {
    private int i;

    public void a() {
        int old_i = i;
        i = i++;
        assertEquals(old_i + 1, i);
    }
}
Try answering each of these before you scroll down, and for each one be prepared to draw the CPU instructions involved and show where another thread can interrupt them or where reads and writes can be reordered:
- Can the assert ever fail with one thread?
- Can the assert ever fail with multiple threads?
- If you move the calculation to a constructor, does this change your answer?
- If you move it to a static constructor, does this change your answer?
- If
iis a 16 bit vs 32 bit vs 64 bit integer, does this change your answer? - Does ARM vs x86 change your answer?
- If
iis marked asvolatile, does this change your answer? - What does it mean that CPU reads and writes can be reordered?
- Fix the code, and write it as a thread safe singleton.
2. The Answers
2.1 Can the assert ever fail with one thread?
It does not just “ever” fail with one thread; it fails every single time, and that is the trap. In Java the postfix operator i++ saves the current value of i, increments the variable, and then returns the saved value as the result of the expression. The assignment runs last and writes that saved value back into i, so the increment is overwritten by the very assignment that was supposed to keep it. If i was 5 before the line, i++ bumps it to 6, evaluates to 5, and then i = 5 puts it straight back. The bytecode makes it obvious: the old value is pushed onto the operand stack before the increment, and that stack value is what gets stored.
// javap -c output for i = i++ on a field
aload_0            // 'this' for the outer assignment
aload_0            // 'this' for the increment
dup
getfield  i        // push old value of i (5) onto the stack
dup_x1             // tuck a copy of 5 underneath as the value of i++
iconst_1
iadd
putfield  i        // i = 6
putfield i // then store the saved 5: i = 5sequenceDiagram
participant Field as i (field)
participant Stack as operand stack
Note over Field: i = 5
Field->>Stack: getfield pushes the old value, 5
Note over Field: the increment stores i = 6
Stack->>Field: the assignment stores the saved 5, i = 5
Note over Field: assert expects 6, finds 5, failsI ran this rather than trusting memory, and it prints old=5 new=5 assert=false. Most IDEs and static analysers (IntelliJ, SpotBugs, Sonar) will flag the line, which is a good thing to mention in the interview. In C the same line is undefined behaviour because it modifies i twice without a sequence point; C++ made it well defined in C++17, and the defined result is the same as Java: i is unchanged.
So the first thing the candidate should do is fix the bug, because every remaining question is more interesting once the code means what the author intended:
public void a() {
    int old_i = i;
    i++;                          // or i = i + 1, but never i = i++
    assertEquals(old_i + 1, i);
}
With the fix in place and a single thread, the assert holds for int. The interesting single threaded edge is overflow. Java integer arithmetic always wraps silently, so at Integer.MAX_VALUE the increment wraps to Integer.MIN_VALUE, but old_i + 1 wraps in exactly the same way, both sides agree and the assert still passes. If you wanted overflow to be an error you would have to use Math.incrementExact, which throws an ArithmeticException instead. Keep that overflow point in your back pocket, because it becomes important in answer 2.5.
2.2 Can the assert ever fail with multiple threads?
Yes, and in two quite different ways. The first is that i++ is not one operation; it is a read, a modify and a write, and another thread can run between any two of those steps. The second is that even if the increment itself were atomic, the assert reads i again afterwards, and by then another thread may have incremented it too, so the value you compare against is not the value you produced.
There is also a third, more Java specific problem. Without synchronisation there is no happens before relationship between the threads, so the Java Memory Model allows the JIT to keep i in a register, hoist the read out of a loop, or merge several increments into one. The program is a data race, and the JMM gives you very few guarantees about what a racy read returns beyond “some value that was written at some point”.
On x64, HotSpot’s C2 compiler will typically turn i++ on a field into something like this:
mov  eax, dword ptr [rsi+0xc]   ; LOAD  i into a register
inc  eax                        ; ADD 1 in the register
mov  dword ptr [rsi+0xc], eax   ; STORE the register back to i
It helps to be precise about how many times a() actually reads i, because it is three, not one. There is the snapshot read into old_i, the read inside i++, and the read inside assertEquals after the increment. Another thread can change i in either gap between those reads, and each gap produces a different failure.
The first failure is the lost update. Put two threads on two cores, let both take their snapshot and their increment read while i is 5, and both compute 6 and store 6. One increment simply vanishes, and both asserts can still pass, because each thread compares the 6 it finds against its own old_i + 1, which is also 6.
sequenceDiagram
    participant A as Thread A (core 0)
    participant M as i in memory
    participant B as Thread B (core 1)
    Note over M: i = 5
    A->>M: read 1, snapshot old_i = 5
    B->>M: read 1, snapshot old_i = 5
    A->>M: read 2, i++ loads 5
    B->>M: read 2, i++ loads 5
    A->>M: STORE 6
    B->>M: STORE 6, A's increment is lost
    A->>M: read 3, assert sees 6 (equals 5+1, passes)
    B->>M: read 3, assert sees 6 (equals 5+1, passes)
    Note over M: two increments ran, i only moved by one, and no assert fired
The second failure needs no lost update at all. Thread A takes its snapshot of 5, and before its i++ runs, thread B completes a whole increment and moves i to 6. Thread A’s increment then reads 6 and correctly stores 7, so the counter is right, yet A’s assert compares 7 with old_i + 1, which is 6, and fails. The same thing happens if B sneaks in between A’s store and A’s assert read. Here the assert is reporting a problem with the test rather than with the count.
sequenceDiagram
    participant A as Thread A (core 0)
    participant M as i in memory
    participant B as Thread B (core 1)
    Note over M: i = 5
    A->>M: read 1, snapshot old_i = 5
    Note over A: A is preempted before i++
    B->>M: B runs all of a(), stores 6, its assert passes
    A->>M: read 2, i++ loads 6
    A->>M: STORE 7, nothing was lost
    A->>M: read 3, assert sees 7 (expects 5+1 = 6, fails)
    Note over M: i = 7 is correct, but the assert fails anyway
Put those two diagrams side by side and you get the uncomfortable conclusion: in this code the assert can fail when the counter is right, and pass when the counter is wrong. It is not measuring the thing it claims to measure.
The same thing happens on a single core machine, because the scheduler can preempt a thread after the load and before the store, so “multiple threads” is the condition that matters, not “multiple cores”. When I ran four threads doing two million increments each on a two core box, the counter ended up nearly a million short of eight million and a handful of asserts fired, which is exactly the shape you would expect: lost updates are common, and assert failures need the unlucky reread timing. On another run of the demo script in answer 2.9, the counter was 300,000 short and not a single assert fired, which is the most dangerous outcome of all: the test passes and the data is wrong.
2.3 If you move the calculation to a constructor, does this change your answer?
It depends entirely on what i belongs to, and that is the point of the question. If i is an instance field, then while a constructor is running nobody else normally has a reference to the object, so there is no second thread that could touch this particular i and the fixed code cannot fail. The original i = i++ still fails, of course, because that bug never needed a second thread.
There are two ways to break that comfort. The first is letting this escape during construction: starting a thread inside the constructor, registering a listener, adding this to a static collection, or passing it to a callback. Once another thread holds the reference before the constructor finishes, you are back to answer 2.2, and on top of that it can see fields in a half initialised state. The second is when i is a static field and the constructor increments it, which is a common way people try to count instances. Many threads can construct objects at the same time, they all share the one static i, and you have the exact race from answer 2.2 wearing a different coat.
public class Foo {
    private static int instances;      // shared by every Foo

    public Foo() {
        int old = instances;
        instances++;                    // races with every other constructor
        assert instances == old + 1;    // only checked when run with java -ea
    }
}
Java adds a subtlety here that is worth raising unprompted, called unsafe publication. If one thread constructs an object and stores the reference in a plain shared field, another thread can see the reference before it sees the writes made inside the constructor, so it can observe i at its default value of 0 even though the constructor set it. The JMM only guarantees that a thread which sees the reference also sees the constructor’s writes for final fields (JLS 17.5), or when the reference is published safely: through a volatile field, a synchronized block, a concurrent collection, or a static initialiser.
sequenceDiagram
    participant T1 as Constructing thread
    participant M as Memory
    participant T2 as Reading thread
    T1->>M: allocate Foo, fields default to 0
    T1->>M: STORE shared = reference (becomes visible early)
    T2->>M: LOAD shared, gets the reference
    T2->>M: LOAD shared.i, sees 0
    T1->>M: STORE i = 1 from the constructor (visible too late)
    Note over T2: a final field would have guaranteed T2 sees 1
2.4 If you move it to a static constructor, does this change your answer?
Java does not call it a static constructor, it calls it a static initialiser, but the answer is yes, and this is the most useful thing to know about it. JLS 12.4.2 specifies that class initialisation happens at most once and is protected by an initialisation lock. If a second thread touches the class while the static initialiser is still running, that thread blocks until it finishes, and the completion of class initialisation happens before any use of the class by other threads. That means the increment inside a static block cannot race with any other code that goes through the class, and the result is safely published to everyone. The fixed version cannot fail there; the original i = i++ still fails, because a static block does not change what the expression means.
public class Foo {
    private static int i;

    static {
        int old_i = i;
        i++;                        // runs once, under the JVM's class initialisation lock
        assert i == old_i + 1;
    }
}sequenceDiagram
participant T1 as Thread 1
participant RT as JVM class initialisation lock
participant T2 as Thread 2
T1->>RT: first active use of Foo, takes the lock
Note over T1: static block runs, i goes from 0 to 1
T2->>RT: touches Foo, blocks
T1->>RT: initialisation completes, releases
RT->>T2: proceeds, guaranteed to see i = 1There are sharp edges worth naming in an interview. A static block can only touch static fields, so if i is an instance field the code does not compile. If the static block throws, the first caller gets an ExceptionInInitializerError, the class is marked as erroneous, and every later attempt to use it throws NoClassDefFoundError for the lifetime of that class loader, which is a famously confusing error to debug in production. And if two classes have static initialisers that depend on each other and are initialised from different threads, you can deadlock, while within one thread you can observe a static field at its default value because the JVM will not restart an initialisation that is already in progress. The static initialiser is a great tool for one time setup and a terrible place for anything clever.
2.5 If i is a 16 bit vs 32 bit vs 64 bit integer, does this change your answer?
It changes it in three different places, and the 16 bit case is the one that catches people out on a single thread.
2.5.1 The 16 bit trap: binary numeric promotion
Java has no arithmetic on short; binary numeric promotion widens both operands to int first. i++ on a short is defined as adding one and then narrowing back, so when i holds 32767 it becomes -32768. Meanwhile old_i + 1 is computed as an int, gives 32768, and stays 32768 because nothing narrows it. Whatever assertion you use, the comparison happens after both sides are promoted to int, so it compares 32768 with -32768 and fails, with one thread and the bug fixed. This is a language rule, not a quirk of the test library: even a bare i == old_i + 1 is false. My check printed old=32767 new=-32768 assert=false.
short i = Short.MAX_VALUE;
short old_i = i;
i++;                                       // 32767 + 1 wraps to -32768
assertEquals(old_i + 1, i);                // int 32768 vs int -32768: fails
assertEquals((short) (old_i + 1), i);      // passes, both wrap identically
For int and long the right hand side stays the same width as the field, both sides wrap identically, and the single threaded assert holds.
2.5.2 The 64 bit trap: torn reads and writes
JLS 17.7 says that a single write to a non volatile long or double may be treated as two separate 32 bit writes, so another thread can observe a torn value: the new low half with the old high half. Writes and reads of volatile long and volatile double are always atomic, and so are references. In practice, every mainstream 64 bit JVM does atomic 64 bit loads and stores, and the specification encourages implementations to do so, but the language does not promise it, and 32 bit JVMs on 32 bit hardware genuinely can tear. If i sits at 0x0000_0000_FFFF_FFFF and someone increments it to 0x0000_0001_0000_0000, a reader can see 0x0000_0001_FFFF_FFFF or 0x0000_0000_0000_0000, values that never existed in your program, which makes old_i nonsense before you even get to the race.
sequenceDiagram
    participant W as Writer (32 bit JVM)
    participant M as long i in memory
    participant R as Reader
    Note over M: high = 0x00000000, low = 0xFFFFFFFF
    W->>M: STORE low half = 0x00000000
    R->>M: LOAD low half (0x00000000)
    R->>M: LOAD high half (0x00000000)
    Note over R: reads 0, a value nobody ever wrote
    W->>M: STORE high half = 0x00000001
2.5.3 What size does not change
Size does not rescue you from the read modify write race. A 16 bit, 32 bit or 64 bit i++ is still a load, an add and a store, so the multithreaded answer in 2.2 is unchanged for every width.
2.6 Does ARM vs x86 change your answer?
It does not change whether the code is correct; the unsynchronised version is broken on both, because the JMM is the contract and it says a data race has no ordering or atomicity guarantees regardless of the hardware underneath. What the hardware changes is how the increment is built, how likely you are to see the failure, and which other surprises you can hit.
On x86, an arithmetic instruction can operate directly on memory, as in inc dword ptr [rsi+0xc]. Interrupts are only taken between instructions, so on a single core that one instruction cannot be split by a context switch. That is a statement about interruptibility, not atomicity. Without the lock prefix the instruction is not architecturally atomic with respect to other cores: it reads the cache line and writes it back as separate steps, and another core can write in between. The lock prefix is what makes the processor hold the cache line exclusively for the whole read modify write. Whether C2 emits the single instruction or a separate load, add and store is its choice, so you can never rely on it.
ARM is a load and store architecture, which means arithmetic never touches memory directly. An increment is always at least three instructions, and making it atomic needs either an exclusive load and store retry loop, or the single instruction atomics added in ARMv8.1 (the LSE extension), which HotSpot can use when the hardware supports them.
; ARM64, plain increment: three separate steps, never atomic
ldr   w1, [x0, #12]       ; LOAD
add   w1, w1, #1          ; ADD
str   w1, [x0, #12]       ; STORE

; ARM64, atomic increment without LSE: retry until nobody interfered
retry:
ldaxr w1, [x0]            ; LOAD with acquire, and mark the cache line exclusive
add   w1, w1, #1
stlxr w2, w1, [x0]        ; STORE with release, only succeeds if still exclusive
cbnz  w2, retry           ; someone else wrote in between, go again

; ARM64 with LSE: one instruction
ldaddal w3, w1, [x0]      ; atomically add w3, return the old value in w1

; x86: AtomicInteger.incrementAndGet becomes one locked instruction
lock xadd dword ptr [rsi+0xc], eax
The bigger difference is memory ordering. x86 uses a strong model called Total Store Order, where the only reordering the hardware does is to let a load complete before an earlier store to a different address. ARM is weakly ordered: for ordinary loads and stores to normal memory, with no address, data or control dependency between them and no barrier or acquire and release instruction, the architecture permits all four combinations to be observed out of order by another core. Dependencies and barriers constrain that, but plain Java field accesses in racy code give you neither, so in practice ARM allows substantially more observable reorderings than x86 TSO. That means a racy piece of code that seems fine on an Intel laptop can fail on a Graviton server or an Apple Silicon Mac, which is exactly why “it works on my machine” is not evidence for concurrent code. Answer 2.8 shows what this looks like.
2.7 If i is marked as volatile, does this change your answer?
It changes several things, but not the one that matters. In Java a volatile field gets three guarantees: all volatile accesses fall into a single total synchronisation order that is consistent with each thread’s program order, and every volatile read sees the last write to that field in that order (which is what people mean when they call volatile sequentially consistent), a volatile write happens before every subsequent volatile read of that field so it publishes everything the writer did before it, and reads and writes of volatile long and volatile double become atomic, which removes the tearing problem from answer 2.5.2. Note that “last in the synchronisation order” is a guarantee about ordering and visibility, not about wall clock time: it does not mean every core agrees on one instantaneous value of i, only that no thread can observe volatile writes in an order that contradicts that single sequence. What it does not do is make i++ atomic. A volatile increment is still a volatile load, an add, and a volatile store, with a gap in the middle that another thread can use, so the lost update from answer 2.2 is completely intact.
sequenceDiagram
    participant A as Thread A
    participant M as volatile int i
    participant B as Thread B
    A->>M: volatile LOAD reads 5
    B->>M: volatile LOAD reads 5
    A->>M: volatile STORE 6
    B->>M: volatile STORE 6
    Note over M: still a lost update, volatile orders and publishes but does not make i++ atomic
Because volatile accesses are sequentially consistent, Java’s volatile even forbids the store then load reordering in answer 2.8.1, which is a stronger guarantee than many developers expect. Candidates who come from C or C++ sometimes get this backwards: there volatile has nothing to do with threads at all, and std::atomic is the tool for concurrency. In every one of those languages, though, volatile plus ++ is a bug.
2.8 What does it mean that CPU reads and writes can be reordered?
It means the order in which your program issues loads and stores is not necessarily the order in which other cores observe them. A single thread always appears to run in program order from its own point of view, but another core looking at memory can see a different order. There are three layers doing this. The JIT can reorder, merge or remove memory accesses as long as a single thread cannot tell, and the JMM explicitly permits this for code without happens before edges. The CPU executes out of order and retires in order, but loads can be satisfied early. And most importantly, each core has a store buffer: writes go into a private queue and drain to the cache later, so the core can keep running instead of waiting for the cache line, and its own later loads can complete while its earlier stores are still sitting in that queue, invisible to everyone else.
2.8.1 Store then load: the reordering even x86 allows
This is the classic store buffer test. Both variables start at zero, and each thread writes one and reads the other. Intuitively at least one thread must see a 1, but with plain fields, on x86 and ARM alike, both threads can read 0, because each write is still in its own core’s store buffer when the other core’s read happens.
// int x = 0, y = 0 (plain fields)
// Thread A          // Thread B
x = 1;               y = 1;
int r1 = y;          int r2 = x;
// r1 == 0 && r2 == 0 is possiblesequenceDiagram
participant A as Core 0
participant SBA as Core 0 store buffer
participant MEM as Shared cache / memory
participant SBB as Core 1 store buffer
participant B as Core 1
Note over MEM: x = 0, y = 0
A->>SBA: STORE x = 1 (parked in buffer)
B->>SBB: STORE y = 1 (parked in buffer)
A->>MEM: LOAD y, reads 0
B->>MEM: LOAD x, reads 0
SBA->>MEM: x = 1 drains, too late
SBB->>MEM: y = 1 drains, too late
Note over A,B: r1 = 0 and r2 = 0, as if each load ran before its own storeDeclaring x and y as volatile in Java forbids this outcome. On x86, HotSpot implements that by following each volatile store with a full fence (a lock addl on the stack, or an mfence), which drains the store buffer before the next load. That fence is also why volatile writes cost noticeably more than volatile reads on Intel.
2.8.2 Store then store and load then load: what ARM adds
x86 never reorders two stores, and never reorders two loads, so the following message passing pattern with plain fields usually works there, although the JIT is still entitled to break it. ARM can reorder both, so the consumer can see the flag before the data and print 0.
// Producer           // Consumer
data  = 42;           if (ready)
ready = true; System.out.println(data); // can print 0 on ARMsequenceDiagram
participant P as Producer core
participant MEM as Memory as seen by the consumer
participant C as Consumer core
P->>MEM: STORE data = 42 (delayed)
P->>MEM: STORE ready = true (becomes visible first)
C->>MEM: LOAD ready, sees true
C->>MEM: LOAD data, sees 0
Note over MEM: data = 42 finally becomes visibleThe fix is to say what you mean. Mark ready as volatile, and the write of ready = true happens before any read that sees true, which drags the write of data along with it. If you want only the minimum ordering, VarHandle.setRelease and getAcquire give you release and acquire without the full fence. synchronized blocks and the java.util.concurrent.atomic classes include the necessary barriers, which is why code that only touches shared state inside a lock never has to think about any of this.
2.9 Fix the code and write it as a singleton
Here is the whole thing fixed, with i at class scope inside a thread safe singleton. The singleton uses the initialisation on demand holder idiom, which is the static initialiser guarantee from answer 2.4 put to work: the Holder class is not initialised until getInstance() first touches it, the JVM’s class initialisation lock makes the construction happen once, and the result is safely published to every thread without any volatile or double checked locking.
I am showing three versions of the increment because they answer the interview question in different ways. The synchronized version keeps the original shape, including rereading i in the assert, and it is correct because every access to i goes through the same monitor, so nobody can change it between the increment and the check. The lock free version uses compareAndSet, which atomically replaces the value only if it still equals what we read, so when it succeeds we know our write replaced exactly observed and nothing came in between. The third is what you would actually ship.
import java.util.concurrent.atomic.AtomicLong;

public final class Counter {

    private Counter() { }

    // Initialisation on demand holder: lazy, thread safe, no locks on the read path.
    private static final class Holder {
        static final Counter INSTANCE = new Counter();
    }

    public static Counter getInstance() {
        return Holder.INSTANCE;
    }

    // Version 1: keep the interview shape, guard every access with one monitor.
    private long i;                          // class scope, only touched while holding 'this'

    public synchronized long incrementLocked() {
        long old_i = i;
        i++;
        assert i == old_i + 1;               // safe: no other thread can touch i in here
        return i;
    }

    public synchronized long valueLocked() {
        return i;
    }

    // Version 2: lock free. Retry until our compare and swap wins.
    private final AtomicLong atomic = new AtomicLong();

    public long incrementLockFree() {
        long observed, desired;
        do {
            observed = atomic.get();
            desired = observed + 1;
        } while (!atomic.compareAndSet(observed, desired));

        // We swapped observed for desired atomically, so our increment is exactly +1.
        // Do NOT reread atomic.get() here and compare: another thread may already have moved it.
        return desired;
    }

    // Version 3: what you would actually ship.
    public long increment() {
        return atomic.incrementAndGet();
    }

    public long value() {
        return atomic.get();
    }
}
Notice that the locked version and the atomic versions use different fields, and that is deliberate. If one method updates a field under synchronized and another updates the same field with an atomic operation, the monitor no longer protects the assert, because the atomic writer never takes it. Pick one discipline per field and stick to it. A last practical note: Java’s assert statement is disabled by default and only runs with java -ea, so an interview answer that relies on assert to catch a race in production is relying on something that is not even executing. If the counter is extremely hot and you only need the total occasionally, java.util.concurrent.atomic.LongAdder spreads the increments across cells to avoid every core fighting over one cache line.
If you want to see the broken and fixed versions side by side, this script writes a single file Java program and runs it with the JDK’s source launcher (Java 11 or later), hammering each implementation from several threads.
cat > race_demo.sh << 'EOF'
#!/usr/bin/env bash
set -euo pipefail

cat > RaceDemo.java << 'JAVA'
import java.util.concurrent.atomic.AtomicInteger;
import java.util.concurrent.atomic.AtomicLong;

public class RaceDemo {
    static final int THREADS = 8;
    static final int PER_THREAD = 1_000_000;

    // Fixed i = i++, but still racy.
    static class Broken {
        int i;
        final AtomicInteger failures = new AtomicInteger();
        void a() {
            int old_i = i;
            i++;
            if (i != old_i + 1) failures.incrementAndGet();
        }
    }

    static final class Counter {
        private Counter() { }
        private static final class Holder { static final Counter INSTANCE = new Counter(); }
        static Counter getInstance() { return Holder.INSTANCE; }

        private long i;
        final AtomicInteger failures = new AtomicInteger();
        synchronized void a() {
            long old_i = i;
            i++;
            if (i != old_i + 1) failures.incrementAndGet();
        }
        synchronized long value() { return i; }

        private final AtomicLong atomic = new AtomicLong();
        long incrementLockFree() {
            long observed, desired;
            do { observed = atomic.get(); desired = observed + 1; }
            while (!atomic.compareAndSet(observed, desired));
            return desired;
        }
        long atomicValue() { return atomic.get(); }
    }

    static void run(Runnable body) throws InterruptedException {
        Thread[] ts = new Thread[THREADS];
        for (int t = 0; t < THREADS; t++) {
            ts[t] = new Thread(() -> { for (int k = 0; k < PER_THREAD; k++) body.run(); });
            ts[t].start();
        }
        for (Thread t : ts) t.join();
    }

    public static void main(String[] args) throws Exception {
        int x = 5;
        x = x++;
        System.out.println("i = i++ on 5 leaves " + x);

        short s = Short.MAX_VALUE;
        short olds = s;
        s++;
        System.out.println("short at 32767: old_i + 1 = " + (olds + 1) + ", i = " + s
                + ", equal = " + (olds + 1 == s));

        long expected = (long) THREADS * PER_THREAD;

        Broken broken = new Broken();
        run(broken::a);
        System.out.printf("Broken    : expected %,d, got %,d, assert failures %,d%n",
                expected, broken.i, broken.failures.get());

        Counter c = Counter.getInstance();
        run(c::a);
        System.out.printf("Locked    : expected %,d, got %,d, assert failures %,d%n",
                expected, c.value(), c.failures.get());

        run(c::incrementLockFree);
        System.out.printf("Lock free : expected %,d, got %,d%n", expected, c.atomicValue());
    }
}
JAVA

java RaceDemo.java
EOF
chmod +x race_demo.sh
./race_demo.sh
3. The Answers at a Glance
| Scenario | Can the assert fail? | Why |
|---|---|---|
Original i = i++, any setup | Always | The assignment writes back the old value, so i never changes |
Fixed i++, one thread, int or long | No | Both sides wrap identically at the maximum value |
Fixed i++, one thread, short at 32767 | Yes | i wraps to -32768, old_i + 1 is promoted to the int 32768 |
Fixed i++, multiple threads, no synchronisation | Yes | Three separate reads of i; lost updates and stale assert reads |
Instance constructor, this never escapes | No | No other thread can reach this object’s i |
| Constructor incrementing a static field | Yes | Every constructing thread shares the one field |
| Static initialiser | No | JVM class initialisation runs once under a lock |
Non volatile long, multiple threads | Yes | The race, plus torn reads permitted by JLS 17.7 |
| ARM instead of x86 | Yes, as on x86 | Weaker ordering makes failures more likely, but x86 is already unsafe |
volatile int | Yes | Ordering and visibility, but i++ is still load, add, store |
Every access to i inside one synchronized monitor | No | Nobody can change i between snapshot, increment and check |
AtomicLong CAS, checking the value the CAS returned | No | The swap proves exactly observed was replaced by observed + 1 |
AtomicLong, then rereading get() for the assert | Yes | The increment is atomic, but the reread is a separate operation |
4. What the Question Is Really Testing
None of these answers require memorising the JLS or the Intel manual. What the question rewards is a habit of asking what a line of code turns into, who else can see the memory it touches, and what each layer (the language, the Java Memory Model, the JIT and the CPU) actually promises, as opposed to what you assume it promises. The candidates who do well are the ones who notice that i = i++ is wrong before anything else, who treat i++ as three operations rather than one, who know that volatile buys visibility and ordering but not atomicity, and who reach for synchronized or java.util.concurrent.atomic when they need the increment to be indivisible.
But the most interesting thing this question reveals is not whether someone knows Java, or even whether they understand concurrency. It is whether they know the difference between what they have observed and what they can guarantee. Listen to how people defend code like this, and you hear the same handful of sentences: “I have never seen it fail”, “it works on Intel”, “we tested it with eight threads”, “we marked the field volatile”, “the assertion passed”. Every one of those statements can be completely true while the implementation is still wrong, and the demo in answer 2.9 proves it, with a test that passed while three hundred thousand increments quietly disappeared. Observation tells you what happened on one machine, on one run, under one schedule; a guarantee comes from the language specification, the memory model and the synchronisation you actually wrote. The engineers worth hiring are the ones who can tell those two things apart, and who refuse to ship on the strength of the first when the problem demands the second. That is the difference between someone who can write code and someone who can reason about whether a system is correct.
Really enjoy your posts and understanding the fundamentals in any field is important. Are these types of interview questions aimed at all developer levels to test their problem solving. I could answer some of the questions posed however the rest stumped me. Then I turned to Co-Pilot and the responses were brilliant. I am a huge football fan so where content stumps I ask for an analogous football response. The analogy first than what Co-Pilot recommended I should be doing at my age group.
Football analogy ⚽
Nobody expects a modern striker to know how to:
Stitch a football
Grow the grass
Build the stadium
But they must understand:
Positioning
Space
Timing
Strategy
Likewise:
You don’t need to remember every Java corner case.
You do need to know enough fundamentals to recognise when AI is talking nonsense.
Co-Pilots Recommendation based on its memory of me
So, my honest view, Michael:
At 47, with TOGAF certifications, a master’s degree, and years in banking and telecom architecture, I’d spend 10% of my learning time on low-level fundamentals and 90% on business, architecture, AI, economics, operating models, and transformation.
Those are the areas where AI is currently a co-pilot.
The Java increment operator stuff? That’s increasingly becoming AI’s job to remember. 😉 …. As always thanks for moving us forward!