Two Prices for the Same Model: Building Claude Burst
A flat Claude subscription can cost far less than the equivalent API usage for heavy users. Reconstructing one month of Claude Code session usage with local tooling showed that the same token volume, priced at public API rates, totalled several times the fixed monthly subscription price, meaning heavy users effectively consume API capacity worth a large multiple of what they pay.
I recently ran a comparison out of curiosity: what would a normal month of Claude Code usage on a fixed subscription have cost if it had instead been billed at public API rates. I built some local tooling to reconstruct that from session usage, because the standard analytics were not giving me the visibility I wanted into what individual sessions were actually consuming. That tooling is also open source, a live cost and usage panel that sits next to the terminal and prices every turn as it happens rather than waiting for an end of month invoice: github.com/andrewbakercloudscale/ai-agent-cost-usage-panel.
The result was startling. A heavy user on a flat monthly subscription had generated a token volume that, translated into public API pricing, worked out to a large multiple of what the subscription itself costs, and that gap looked impossible at first, since either my measurement was badly wrong, or Anthropic was selling the same intelligence through two commercial models whose economics were radically different.
The answer turns out to be more interesting than either explanation, and building something around that answer turned out to be a longer job than the idea itself suggested. What I built is called Claude Burst, and it is open source: github.com/andrewbakercloudscale/claude-burst.
1. Claude does not really have one price
When people say that Claude costs a certain amount, they are usually mixing together several very different products. Anthropic sells access to the same broad model family through subscriptions, through its metered API, through enterprise products, and through cloud providers such as Amazon Bedrock. The model may be recognisably the same, but the commercial contract around each route is not.
Claude Max is a fixed monthly subscription that includes Claude Code. It is not unlimited, since Anthropic applies rolling session limits that reset every five hours, weekly limits, and potentially other capacity controls, whereas API access is explicitly metered, so the more tokens you consume, the more you owe.
Amazon Bedrock also provides metered access to Anthropic models, but the bill arrives through AWS rather than directly from Anthropic.
| Route | Commercial model | What stops you | Typical identity |
|---|---|---|---|
| Claude Max | Fixed monthly subscription | Five hour, weekly and other usage limits | Individual Claude login |
| Anthropic API | Metered token consumption | Rate limits, spend limits or your budget | API or platform credential |
| Amazon Bedrock | Metered cloud consumption | AWS quotas, policy or your budget | AWS credential or Bedrock API key |
This means that asking what Claude “costs” is already the wrong question. A better question is what Claude costs through a particular commercial channel for a particular workload shape.
2. Does a large API equivalent value mean Anthropic is losing money on that account?
No, and this is the first distinction that matters. An API equivalent cost estimate answers a hypothetical question: what would this observed token mix have cost if it had been charged at public API list prices? It does not tell us Anthropic’s marginal cost of inference, its internal cost of compute, the effect of capacity commitments, its gross margin, or the economics of serving a subscription user during otherwise underutilised capacity.
The quality of the estimate also depends heavily on the measurement. Claude Code makes extensive use of prompt caching, so a tool that simply multiplies every input token by the normal input token price can significantly overstate the equivalent API bill, and a credible calculator needs to distinguish uncached input, cache writes, cache reads, output tokens, the model used, and any other pricing buckets that matter at the time.
My point is therefore not that Anthropic is necessarily losing money on any particular subscriber. The point is that the public value of the consumption, when translated into another Anthropic pricing model, can be dramatically larger than the subscription fee, and that pricing discontinuity is real even if Anthropic’s internal cost is far below the API equivalent number.
3. Why would Anthropic price it this way?
The most useful way to think about Max is not as cheap API access. It is closer to a bounded block of interactive capacity sold to one human.
Anthropic controls the risk through time windows, weekly allowances, model limits and other usage constraints, and a human developer also consumes capacity differently from a production API workload that can fan out thousands of requests, run continuously, serve external customers and create much less predictable concurrency. The API customer is buying something different even if the underlying model weights are the same.
There is also straightforward market segmentation. A fixed subscription gives an individual a psychologically simple price and encourages deep adoption, while API pricing captures value from workloads that scale with software rather than with one person’s working day, and enterprise products add administration, contractual controls, governance and support on top of the model access itself.
This is common in computing, and the interesting part is the size of the gap that appears once coding agents become heavy consumers of tokens, because a single strong engineer can now generate an amount of inference that would once have looked like a small application workload.
4. The obvious architecture is Max first, metered overflow second
Once I understood the distinction, the architecture became almost embarrassingly obvious.
Suppose an engineer has their own Max subscription and uses Claude Code interactively. While that subscription has capacity, use it. When Anthropic itself says that the five hour or weekly allowance has been exhausted, stop sending that engineer’s inference through the subscription and route the overflow to the same Claude model through Amazon Bedrock.
When the subscription window resets, move the engineer back automatically, and the cost equation becomes very simple:
effective monthly cost = Max subscription + actual metered overflow
You are no longer choosing between Claude Max and Bedrock. You are using them as two capacity tiers for the same underlying model family, where Max becomes the included base capacity and Bedrock becomes the burst layer.
This is conceptually similar to many infrastructure patterns we have used for years, where you consume the cheaper bounded capacity first, then pay an on demand rate only for the demand that exceeds it.
5. Anthropic already exposes the pieces required to build this
I initially assumed that implementing the idea would require an ugly wrapper around Claude Code, and it does not.
Anthropic’s current Claude Code documentation explicitly supports an LLM gateway through the ANTHROPIC_BASE_URL configuration. More importantly, the documentation says that if you set only the base URL and do not provide a replacement gateway credential, Claude Code keeps using the developer’s saved claude.ai subscription login, so requests pass through the gateway while the normal subscription usage limits and billing still apply.
That gives us exactly the interception point we need, since Claude Code also exposes the five hour and seven day subscription windows together with their reset timestamps, and distinguishes account usage limits from temporary server throttling. That means a router does not need to guess when somebody is close to a limit, scrape a web page, or estimate the window from local logs. It can wait until Anthropic says the allowance has actually been rejected, record Anthropic’s own reset time, replay that request to Bedrock, and remain on Bedrock until the window opens again.
There is one subtle but important rule here: a plain HTTP 429 is not enough. Anthropic also uses 429 responses for temporary server side throttling and other limits, so automatically converting every 429 into paid Bedrock traffic would be both technically sloppy and potentially expensive, and the router should switch only when the subscription specific quota state says that the included allowance is genuinely exhausted.
6. Checking this against Anthropic’s actual terms
That distinction between a genuine subscription rejection and ordinary throttling matters technically, and it also matters contractually, so it is worth checking against what Anthropic actually documents and has enforced, rather than against intuition alone.
The design does not attempt to make Max deliver more than Anthropic has allowed. It does not rotate accounts, share one user’s credentials across a team, modify Anthropic’s quota headers, fake a reset, or suppress a rejection. Once Max says no, that Max channel is treated as unavailable until Anthropic’s own reset time, and the next request is a separate, properly authenticated request through Amazon Bedrock, using a Bedrock credential the organisation already holds rather than the subscription’s own token.
That distinction lines up closely with how Anthropic itself describes this pattern. Anthropic’s Claude Code documentation states directly that pointing the base URL at a gateway without supplying a separate gateway credential does not replace the subscription, because the saved claude.ai login remains the active credential and its usage limits and billing still apply. That is precisely the mechanism Claude Burst relies on for the Max side of the routing, described by Anthropic as a supported configuration rather than discovered as a workaround.
The enforcement actions that have actually happened against subscription usage in 2026 are aimed at something different. Anthropic has repeatedly acted against tools that extract the OAuth token from a Claude Pro or Max login and hand it to a separate, unofficial client, so that client can call Anthropic’s API while impersonating Claude Code. That is credential extraction, and it is what got those tools blocked. Claude Burst does not do this, since the real claude binary is what runs, Claude Code’s own request and its own OAuth headers pass through the local gateway untouched on the Max path, and the only place a different credential is introduced is the Bedrock overflow path, where the organisation’s own AWS credential authenticates a separately billed request rather than impersonating the subscription.
The Consumer Terms’ catch all clause against bypassing Anthropic’s systems or protective measures is the one worth reading most carefully, and the router’s own behaviour is designed around it rather than against it: once Anthropic’s own rate limit response says the allowance is exhausted, the gateway treats that rejection as final for the rest of the window rather than retrying it, disguising it, or working around it, and the overflow to Bedrock happens only after the limit has been respected, never instead of respecting it.
None of this removes the more mundane consumer versus commercial question. Anthropic’s own guidance to users who hit their Max limits during coding work is to switch to metered API credits, and the Consumer Terms note that Claude Pro and Max are offered for individuals or entities, while separate Commercial Terms govern API keys and Console access. That means an organisation running many individual Max subscriptions is still operating under Consumer Terms per account, with each account expected to reflect one engineer’s own ordinary use rather than a shared or automated pool, which is as much a procurement question as a technical one, and it is the reason Claude Burst is built around one Max login per engineer rather than any shared credential.
I am not a lawyer and this is not legal advice, and terms of service are not static either: Anthropic sharpened its own published distinction between the Claude Code CLI and its separate Agent SDK once already in early 2026. A company relying on this pattern at scale should read the current Consumer Terms, Acceptable Use Policy, and Claude Code legal and compliance documentation itself, and treat this section as a starting point for that review rather than a substitute for it.
7. Security controls can change the enterprise calculation, but not the contract
One of the normal reasons to insist on an enterprise AI product is data control, but that control does not actually come from which Anthropic plan sits in the base URL. It comes from where an organisation’s own data loss prevention sits relative to the traffic.
For a setup like this to be safe regardless of whether a given request ends up going to Max or to Bedrock, the inspection needs to sit in one of two places: in front of the terminal itself, so a coding agent’s tool calls and file reads are filtered before they are even assembled into a request, or on the wire between the laptop and the internet, the way a zero trust network access gateway inspects and filters egress traffic regardless of which destination a process is trying to reach. Either position catches an accidental paste of a secret, a customer record, or other regulated data before it leaves the building, and it does so on every route this architecture can take, rather than only the one route an administrator happens to be thinking about that day.
That also means the safety of running something like Claude Burst is not a property of the gateway itself. It is a property of what already sits around it. An organisation with mature, already deployed DLP and zero trust controls sitting in front of the terminal or on the wire can reasonably treat the choice between Max and Bedrock as a cost and capacity decision, because the same inspection already applies to both. An organisation without that maturity should not assume the routing layer gives it any of that protection, because it does not, and should instead assess this case by case, looking at which teams, which data classifications, and which existing controls, if any, actually sit between the engineer’s machine and the model, before deciding whether a fixed subscription plus metered overflow is an acceptable pattern for that team at all.
It does not remove every difference between consumer and commercial products either. Consumer and commercial Anthropic products still have different administration, data processing, retention, and governance arrangements, and those still matter on their own terms. The lesson is simply that a company should identify which controls it genuinely needs from the AI vendor and which controls it already enforces elsewhere, rather than assuming the most expensive commercial route is automatically the safest architecture, or that a cheaper subscription route is automatically unsafe.
8. Building the first version of the router
I have called the experiment Claude Burst, and the first version is deliberately small and Mac only.
Claude Code points to a localhost gateway, the gateway forwards requests to Anthropic using the engineer’s existing Max login, and it watches only the authoritative quota metadata. When Anthropic rejects the subscription allowance, Claude Burst records the reset time and replays the request against the mapped Claude model on Amazon Bedrock.
The Bedrock credential is kept in macOS Keychain. The current MVP uses a Bedrock API key and Amazon’s Anthropic compatible Messages endpoint, which keeps the translation layer much smaller than converting every Claude Code request into the older Bedrock InvokeModel wire format.
The most important behaviour is deliberately conservative, since ordinary 429s do not trigger paid overflow. The code only changes routes when the subscription specific limit is rejected, and it moves back to Max after the exact reset timestamp supplied by Anthropic. There are obvious next steps before this becomes enterprise software, among them replacing long lived Bedrock API keys with AWS SSO and role assumption, testing broader model compatibility, and soak testing the gateway against new Claude Code beta capabilities as Anthropic releases them, which is why I am treating this as an open source experiment rather than pretending the first build is a finished platform.
9. The first version worked, and that was not the same as it being trustworthy
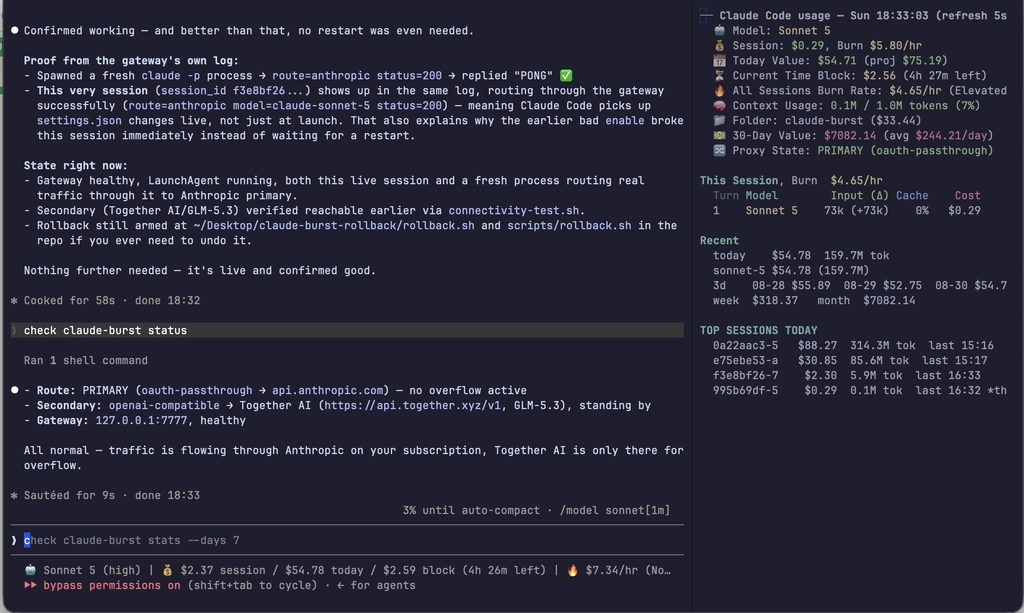
The core routing logic was sound and the first test suite proved the interesting case: a rejected Anthropic request really did get replayed to Bedrock with the model remapped and the OAuth beta header stripped. What it did not have was a way to answer a much more mundane question: if something goes wrong at three in the morning, what actually happened.
The original router had one real log statement, written when overflow activated, recording the claim, the reason and the reset time, and every other branch that could go wrong called an HTTP error response and returned. A body that failed to read, a request over the configured size limit, a Bedrock key missing from Keychain, a model with no entry in the model map, a network error calling either upstream, a failed write to the metrics file, all of these returned a sensible status to Claude Code, but none of them left a trace anywhere on disk.
That is a reasonable shape for a proof of concept. It is not a reasonable shape for something that sits between a paid subscription and a metered AWS bill and decides, unattended, which one an engineer’s inference goes through.
10. Every request now gets a start line and a done line
The fix I wanted was simple to state and slightly fiddly to get right without disturbing the streaming response path. Every request, successful or not, now gets a short id, generated once at the top of the handler and carried through the request’s context, and two lines get written for that id, one when the request starts and one when it finishes, with the finishing line always carrying the actual HTTP status the client received and how long the request took.
The fiddly part was getting the true final status out of a handler that streams a response body directly rather than building it up and writing it once. I wrapped the response writer in a small type that records the first status code written, whether that happens through the header call or through the first write, and still passes flushing through so the server sent events relay loop keeps working exactly as before. The wrapper does nothing except remember what already happened, and it does not change behaviour.
With that in place, a panic recovery wrapper became almost free to add. If anything below panics, a stack trace goes into the log against that same request id, the client gets a clean server error instead of a hung connection or a crashed process, and the done line still gets written, because a local gateway that a developer is relying on to keep working through their session should not be one unhandled error away from taking Claude Code down with it.
11. Naming the failure instead of hiding it
Once every request had a start and a done line, the next pass was going through each early return and giving the operator something to search for: not a generic exception message, but a labelled stage, whether that stage is reading the body, building the outbound request, the upstream call itself, loading the Bedrock key, or mapping the model, with each of those now writing one line naming the stage, the route, and the underlying error before the response goes back to the client.
This matters more than it looks. “Bedrock overflow unavailable” told a user something was wrong, but it did not tell whoever runs the fleet of these gateways whether the problem was a missing environment variable, a Keychain entry that got wiped by an OS update, or Bedrock itself being unreachable. Those are three different follow up actions, and previously they all looked identical from the log file, because there was no log file entry at all.
12. A metrics failure must never become a request failure
The structured metrics file records the route, model, tokens, estimated API equivalent cost, and the reset claim when one applies, and it is written after the response has already been sent to Claude Code. That ordering matters, because it means a failure to write that file, whether from a full disk, a permissions problem, or a configured path that turned out to be a directory, must never turn into a failure of the actual inference request. The old code silently discarded that write error, and it still silently continues past the failure, which is correct, but it now logs the error first, so a slow, quiet loss of metrics does not go unnoticed until someone tries to summarise usage and finds three weeks missing.
The same principle applied to the small local state file that records whether the gateway is currently in overflow. Reading a corrupted state file or failing to write an updated one previously failed silently, and both now log what happened and continue with a safe default rather than either crashing or pretending nothing occurred.
13. Writing tests for the failures, not just the feature
The original test suite proved the feature, and six new tests prove the surrounding behaviour that makes the thing operable.
One confirms that the start and done lines for a single request share the same id, since a log you cannot correlate is barely better than no log at all. One sends an oversized body and checks both the rejection and the specific log line explaining why. One removes the Bedrock credential entirely and checks that the failure is a clear, immediate error with the stage named, rather than a hang. One sends a model with no Bedrock mapping and checks that the error names the offending model. One sends a plain server error from the primary upstream and checks that it passes straight through without being mistaken for a subscription limit, since that distinction is the entire point of the conservative failover design. One points the metrics path at a directory instead of a file and confirms that the actual inference request still succeeds while the failure gets logged. The last one hands the handler a request body that panics on read, a reasonable stand in for a corrupted transport, and confirms that the panic is caught, logged with a stack trace, and turned into a clean error rather than escaping.
All eleven tests pass together, along with a vet check and a race enabled run. Test coverage on the router package sits at fifty two percent, which is an honest number for a project that still has real gaps in it, among them AWS SSO support and broader Bedrock model compatibility testing, rather than a number inflated by testing getters and setters.
14. What did not change, and the one place it now does
The privacy design from the first version stayed exactly as it was through the logging work. Prompts, source code, tool inputs and model outputs are never written to either the log or the metrics file, because logging everything here meant every code path and every failure mode, not the content of the requests themselves. For something that sits in front of a bank’s engineers, that is not a detail to change casually.
There is now one deliberate exception, and it is better stated plainly than discovered. When pauseless compaction (section 18) is switched on, the summary it produces for a long session is saved to ~/.config/claude-burst/compaction-state.json, so that a gateway restart does not throw away a summary that cost a full read of a very large context to produce. That summary is model output derived from the conversation, so it is content, not metadata. Sessions not seen for 48 hours are dropped from the file the next time it is saved, and with compaction switched off, which is the default, nothing of the kind is written at all. Anyone running this under a data classification policy should treat that file the way they treat Claude Code’s own local transcripts, which already hold the full conversation on the same disk.
15. Limits belong to a model, not to an account
The first version treated a subscription rejection as a statement about the whole account: once Anthropic said no, every request went to the paid secondary until the reset time. That was a guess, and it turned out to be an expensive one. Anthropic’s rate limit headers name the bucket that was exhausted, such as five_hour, seven_day_opus or seven_day_overage_included, but nothing in the response says which models that bucket covers. Until 20 September a single refused Fable request armed one account wide window, which sent every model to the paid secondary for the next two days while Opus was still answering normally on the subscription.
Claude Burst no longer guesses in either direction. Only the model that was actually refused gets a window, and if a limit really is account wide, the next model discovers that for itself on its first request, at the cost of one rejection that bills nothing. The rejected request is then replayed down that model’s fallback_chain before anything is spent, so a refused Fable request is retried on Opus 5.5, still on the subscription and still included, and only when every rung in the chain is inside a rejection window of its own does the request go to the metered secondary. The shipped default only steps from Fable to Opus 5.5. Stepping from Opus down to Sonnet works the same way, but it is left for an operator to add deliberately, because it is a larger drop in capability than the saving justifies by default.
The forced window used for testing the secondary deliberately bypasses the chain, since its only purpose is to exercise the paid path, and quietly serving a different Claude model instead would defeat the only test that path ever gets.
16. A network change is not an Anthropic outage
A laptop moving from a hotspot to an office network looks, from inside the gateway, remarkably like Anthropic going down, and failing over does not help, because the secondary sits behind the same dead network. On the evening of 21 September exactly that happened: a network switch put a perfectly healthy primary’s traffic behind a secondary that could not answer for five minutes either.
Three rules now keep a local network problem from being treated as a provider problem. A connection that died while pooled, which shows up as a broken pipe on write, is retried once on a fresh connection, because the server never saw the request and resending it is safe, while a reset on the read side is not retried, because the server may already have run it. When the far side is silent rather than refusing, and a control lookup of an unrelated host also fails, the request gets a fast and explicit error instead of waiting on a second dead host. And a window armed by failures rather than by a rate limit lasts sixty seconds, not five minutes, and releases itself the moment the secondary fails at the transport level as well.
A related fix came from watching the gateway live on 8 September. Pressing Escape in Claude Code cancels the request, and because the outbound call carries Claude Code’s own request context, the upstream call is cancelled too. With the transport failure threshold set to one, a single interrupted turn was enough to arm a five minute overflow window and bill the next few minutes of inference to the paid secondary. A request the client itself cancelled is now neither counted as a failure nor replayed, since nobody is waiting for the answer.
17. Trimming the overflow before paying for it
Every overflow request resends the whole conversation to a metered provider, and in a coding session most of that conversation is old tool output: files read an hour ago, test runs long since superseded, directory listings nobody will look at again. Before an overflow request is sent, tool results older than the most recent ten are now replaced with a one line note, and any single result over 40 KB keeps only its beginning and its end. The dashboard’s Context and cache panel carries the switches, reports what was not sent, shows the cache hit rate per route, and turns its verdict red if pruned requests start failing more often than unpruned ones, since a saving that degrades the answer is not a saving.
The subscription is deliberately never pruned this way, and the reason is worth spelling out because it is what led to the next feature. In my own sessions on the primary, roughly 98% of a long session’s context is read from Anthropic’s prompt cache, which is priced at a small fraction of fresh input, while rewriting history forces the whole context to be written to cache again at a premium. A pruning boundary that moves every ten tool results rewrites the history every few turns, and on a cached primary that costs more than it saves. The saving on the primary therefore has to come from rewriting the history once, on purpose, not a little on every request.
18. Pauseless compaction
On a subscription every turn rereads the whole conversation, so a turn at 400,000 tokens of context consumes roughly four times as much of the allowance as a turn at 100,000, and Claude Code only compacts on its own near the end of its one million token window. That means a long session spends most of its later life paying, in allowance, for context it is barely using. Claude Code’s own /compact addresses this, but it stops the session while it summarises, which is exactly the moment in a long piece of work when a developer least wants to wait.
Pauseless compaction, which is experimental and off by default, does the same job without the pause. When a session’s context passes a threshold, 400,000 tokens by default, Claude Burst sends one background request through the primary, using that session’s own login and the same model, asking it to summarise everything before the developer’s latest prompt. The prompt it uses is Anthropic’s recommended summarisation prompt, extended to preserve decisions, constraints, open items and exact details such as names, numbers and wording, and it ends with an instruction not to call any tools, which matters because the tool definitions stay in the request. The summary request resends the history exactly as Claude Code last sent it, so it reads from cache rather than paying for the whole context again. It takes about forty seconds, and the developer keeps working throughout.
From the next plain prompt onwards, Claude Burst sends the summary in place of those older messages. Claude Code keeps its full local history and sees no difference; the <system-reminder> blocks that carry CLAUDE.md and other session context are carried across word for word; and thinking blocks from before the summary are dropped, as Anthropic requires whenever history changes. The swap is only ever applied at a request that ends in a plain user prompt, never in the middle of a tool round, and every later request is checked against a hash of the history the summary was built from, so a /clear, a /compact or a rewind simply makes the summary stop fitting, and requests then pass through untouched. A session is compacted at most once per window, sixty minutes by default, a warning is logged at 300,000 tokens, and the state survives a gateway restart, which is the reason for the file described in section 14.
The economics are the reverse of pruning the primary. The history is rewritten once per window rather than every few turns, so the cost is one summary call and one cache write of a much smaller prefix, after which every later turn reads hundreds of thousands fewer tokens, and on my estimate the rewrite pays for itself within roughly seven to ten turns.
Against the terms discussion in section 6, this is worth stating precisely. The summary request is an ordinary request from the same user, on the same subscription, with that user’s own login, doing the same kind of summarisation Claude Code’s own /compact performs; it counts against the allowance like any other request, and its whole effect is to make the session consume less of that allowance, not to extend it.
19. What the first day of compaction showed
The first real test ran on 29 September, on one long Opus 5.5 session. It compacted twice, once taking 611,000 tokens of context down to 49,000 in a single step with recall of the earlier work intact, which meant every later turn resent 562,000 fewer tokens. Across 148 requests that came to 79 million tokens not resent. Priced at the public cache read rate, which is the honest rate to use because those tokens would otherwise have been served from cache, that is $15.88 of API equivalent value not consumed, against $5.06 for the two summary calls.
Those numbers need the same care as the comparison that opened this post. They are API equivalent figures, and on a subscription what compaction actually saves is allowance rather than cash, which translates into money only in the hours it keeps an engineer off the paid secondary. They come from one session on one day, and a single session is an anecdote, not a benchmark. Both summaries also predate a fix, made the same evening, that has the summary call read the session from cache instead of cutting the history before summarising it, which should bring the cost of a summary down from about $2 to about $0.20; that is an expectation from the pricing, not yet a measurement. And a summary is lossy by construction: “recall intact” was what I observed in that session, not a guarantee for every session, which is why it stays off by default and why the dashboard shows each session’s context before and after its latest summary, alongside the saving per turn.
20. An idea that did not survive contact: token shunting
Not everything added since the first version is still switched on, and the one that was switched off is as instructive as anything that worked. Token shunting was built from Spotify’s published technique: a Claude Code hook refuses whole file reads of large files and tells Claude to delegate the read to a cheap worker model, GLM 5.3 on Together AI in my case, which returns a short answer with line citations, so the bulk of the file never enters the frontier model’s context.
In its first day of real use it blocked twelve direct reads in real projects and delegated none of them. The transcripts showed why. Claude was blocked, noted that windowed reads were still allowed, and read the file in 340 line windows, just under the 350 line threshold. That loophole is part of the source design, not a bug in my implementation, because Claude has to be able to read the exact lines it is about to edit or quote. The saving depends on the model wanting an answer about the code rather than the code itself, and for nearly every large file read in my workload it wanted the code, most of all in security review runs that must read the code in full, which is exactly the kind of work the original article says not to delegate. My own live test had also forced the behaviour it was meant to measure, which is why it passed.
It was switched off on 21 September and removed from the dashboard, with the reasoning recorded in the repository alongside the evidence. The published results I built it from are not wrong; they measure the bulk read case the technique was designed to win, on a different workload. The lesson I took is narrower: a token saving measured on one workload is a hypothesis for another workload, and the only way to test it is to count what actually happened in real sessions rather than in a test that prompts the model to comply.
21. Keeping Claude Code working with the lid shut
A long running Claude Code session, particularly one being driven from a phone through Remote Control, stops the moment a MacBook’s lid closes, because clamshell sleep takes the whole machine down with it. There is now an option to prevent that, off by default. Setting keep_awake_lid_closed keeps a Claude Code session in Ghostty running, and Remote Control reachable, after the lid is shut, and keep_awake_lid_closed_power decides when that applies:
keep_awake_lid_closed_power | Lid shut, plugged in | Lid shut, on battery |
|---|---|---|
ac (default) | stays awake | sleeps as normal |
always | stays awake | stays awake |
Getting this right took more than it looks. The only switch that overrides clamshell sleep is pmset -a disablesleep 1, which needs root; caffeinate and pmset sleep 0 do not do it. That setting is one global value with no per power source form, so the default ac mode runs a small root LaunchDaemon that follows the power source and turns it on when the Mac is plugged in and off when it is unplugged. With the lid shut every window is occluded, which is exactly when macOS throttles an app, so App Nap is also switched off for Ghostty. The previous sleep setting is recorded and restored on removal, ./install.sh uninstall removes the daemon, and claude-burst status reports the flag, the mode, the power source and the machine’s actual state, and flags any drift between them.
The trade is the same shape as transparent mode’s: this changes a machine wide power setting, not something scoped to Claude Code. In always mode a closed laptop on battery never sleeps, which in a bag means heat and a flat battery, and that is why ac is the default. If the daemon is stopped, the last value it set stays in force, so a Mac unplugged while the daemon is down will not sleep with the lid shut until it is running again.
22. The smaller additions
Several smaller pieces have landed alongside these, and each exists because a specific question kept coming up.
Transparent intercept mode, described in section 25.7, is now the recommended mode rather than the optional one, because base URL mode buys its simplicity by disabling Remote Control. Running it safely required two background guards, a gateway watchdog and a root guard that repairs the packet filter redirect. That guard exists because on 7 September the redirect rule vanished from the loaded ruleset, reloaded by endpoint security software on a network change, while the hosts entry stayed, and every process on the Mac lost Anthropic for hours while every indicator stayed green, since each one was reading configuration rather than testing the live path. The general lesson is to guard the outcome rather than the component. The same incident is why there is now a rollback script committed to the repository that needs nothing installed to run, and that verifies Anthropic resolves off the machine before it claims success.
The dashboard now has an Analytics section that files each session’s spend under the repository its Claude Code transcript says it ran in, which answers a question the per request view never could: which piece of work the spend actually went on. Metrics now record cached tokens separately, so the cost estimate distinguishes cache reads from fresh input, and a model with no pricing entry is reported as unpriced rather than free. An optional pair of Claude Code hooks, managed from the dashboard, reads a repository’s HANDOFF.md into a new session at start and has a writer model prepend a dated handover section at close, committing it locally but never pushing. And the installer now offers to install the live cost and usage panel beside Claude Code, which also marks the turn on which a compaction summary landed.
The test suite has grown with all of this, from eleven tests at the end of section 13 to 367 test functions as of 29 September, including end to end tests that build the real binary.
23. The experiment I actually want to run
The interesting number is no longer the theoretical figure from that first comparison. It is the real blended cost of a strong developer over time.
For each engineer I want to measure the API equivalent value consumed while Max is serving requests, the number of times Max actually reaches a hard allowance, the amount of time spent on the metered secondary, and the real cost of that overflow, and after a month the economics should be obvious. Pauseless compaction adds a question the first version could not ask: how much less often does Max reach its allowance at all when long sessions stop rereading context they no longer need.
If a fixed subscription absorbs most interactive coding demand and the secondary only catches occasional bursts, then paying API rates for every token is economically difficult to justify for this workload. If heavy engineers live on the secondary for large parts of the week, the apparent Max advantage will shrink and a commercial enterprise arrangement may be the better answer. Either result is useful because it replaces vendor pricing assumptions with measured workload economics, and now, when that experiment produces a surprising number or an unexpected failover, there will be a log line explaining why.
24. AI pricing is becoming an architecture problem
The broader lesson is that model selection is no longer the only meaningful cost decision in AI engineering. The route to the model can matter as much as the model itself, and so, it turns out, can the shape of the context sent down that route.
Two requests can reach essentially the same Claude intelligence and have radically different economics because one sits inside a fixed subscription allowance and the other is metered token by token, and as AI agents become capable of consuming enormous amounts of context during an ordinary developer’s day, those pricing boundaries become architecture boundaries.
I learned the pricing half of this from a comparison that, at first glance, looked like a measurement error, a subscriber on a flat monthly plan whose usage translated into a large multiple of that plan’s cost at public API rates. I learned the engineering half of it by building something small enough to feel finished after a weekend, and then finding out how much further it is from working to trustworthy, and how many of the ideas added along the way needed to be measured in real sessions before they deserved to stay switched on. The next logical step is not to complain that the pricing makes no sense, but to design around the commercial reality that Anthropic has created, and to build the boring, unglamorous parts, the logging, the error handling, the tests for the failure paths, with the same care as the interesting routing decision at the centre of it.
Use the included capacity, spend less of it on context you no longer need, respect the limit, pay only for the burst that exceeds it, and log everything that goes wrong along the way so you never have to guess.
That may turn out to be a much better way to buy coding intelligence.
25. Installing and setting up Claude Burst
Claude Burst is Mac only and needs macOS on Apple Silicon or Intel, Go 1.23 or later (there is no prebuilt binary, install.sh builds one locally), and either Claude Code already installed and logged into the Pro or Max account you want to route through, or a metered Anthropic API key if you have no subscription at all. You will also need a credential for whichever secondary you choose: a Together AI or OpenRouter API key for an OpenAI compatible secondary, or Amazon Bedrock access to the Claude models you intend to burst to with a Bedrock API key set as AWS_BEARER_TOKEN_BEDROCK.
25.1 Standard install (subscription primary, Bedrock overflow)
This is the setup described through most of this post: Claude Max as included capacity, Bedrock as paid overflow. The repository’s README now leads with Together AI serving GLM as the secondary instead, which is covered in section 25.6; the installer itself still only knows about Bedrock, which is its historical default rather than a recommendation.
git clone https://github.com/andrewbakercloudscale/claude-burst.git
cd claude-burst

export AWS_REGION=us-east-1
export AWS_BEARER_TOKEN_BEDROCK='your-bedrock-api-key'

./install.sh
install.sh builds the claude-burst binary with go build and installs it to ~/.local/bin/claude-burst; stores the Bedrock key in macOS Keychain when AWS_BEARER_TOKEN_BEDROCK is set; writes the initial ~/.config/claude-burst/config.json; updates ~/.claude/settings.json with only ANTHROPIC_BASE_URL=http://127.0.0.1:7777, deliberately adding no Anthropic credential of its own so the saved Max login stays active; creates and starts a macOS LaunchAgent so the gateway survives reboots, adding ~/.local/bin to ~/.zprofile if it is not already on the path; applies the lid closed setting from config.json if it is switched on; and at the end offers to install the live cost and usage panel. Set CLAUDE_BURST_PANEL=yes or no to answer that last question without a prompt.
Restart Claude Code once the installer finishes, since it needs to pick up the new base URL.
25.2 No subscription install (metered API key primary)
If there is no Pro or Max subscription to route through, an Anthropic API key can be the primary route instead. Because both sides are now metered, a single rate limit response should not be enough to flip paid traffic from one provider to another, so this mode fails over on a sustained run of failures rather than on a subscription exhaustion header:
./install.sh
claude-burst configure --primary anthropic-api-key \
  --secondary openai-compatible \
  --secondary-base-url https://api.together.xyz/v1 \
  --secondary-model zai-org/GLM-5.3
TOGETHER_API_KEY='your-key' claude-burst keychain-set --provider together
claude-burst enable
Then set ANTHROPIC_API_KEY in Claude Code’s own settings, in the env block of ~/.claude/settings.json alongside ANTHROPIC_BASE_URL, not in Claude Burst’s own config. The gateway never stores or injects an Anthropic credential itself; it only forwards whatever auth header Claude Code already sent, in exactly the same way it forwards the OAuth header in subscription mode. Bedrock works as the secondary here too, with --secondary bedrock --region us-east-1.
25.3 Verifying it worked
claude-burst status
curl -s http://127.0.0.1:7777/healthz          # base URL mode only
curl -sk https://api.anthropic.com/healthz     # transparent mode: answers from the gateway
claude-burst stats --days 30
claude-burst status confirms the gateway is running, which route it is on, which models are currently refused, and the state of the lid closed setting. In base URL mode the first health check confirms the local listener is up on port 7777. In transparent mode that direct probe will almost always time out, which is expected, because the redirect rule makes its own target port unreachable; probe the real path instead, and a JSON body containing "overflow" confirms it came from Claude Burst rather than Anthropic. It is also worth checking Claude Code’s own /status and /usage views, to confirm it is still using the intended subscription before any failover happens.
25.4 Day to day commands
claude-burst serve                            # run the gateway in the foreground
claude-burst configure --region us-east-1
claude-burst configure --primary anthropic-api-key --secondary bedrock
claude-burst configure --secondary none       # disable overflow entirely
claude-burst configure --failover-strategy subscription-limit+metered-failures
claude-burst keychain-set                     # Bedrock: reads AWS_BEARER_TOKEN_BEDROCK
claude-burst keychain-set --provider together # OpenAI compatible secondary, reads TOGETHER_API_KEY
claude-burst enable
claude-burst disable
claude-burst status
claude-burst reset                            # back to the primary now
claude-burst force-secondary --minutes 15     # exercise the secondary on purpose
claude-burst stats --days 30
claude-burst version

claude-burst configure --keep-awake-lid-closed true|false
claude-burst configure --keep-awake-power ac|always
sudo scripts/lid-awake-root.sh apply ac|always
sudo scripts/lid-awake-root.sh remove
25.5 Configuration file
Everything above ultimately writes to ~/.config/claude-burst/config.json. Older flat fields (anthropic_base_url, bedrock_base_url, model_map, keychain_service) are still read and synthesised into primary and secondary blocks automatically, but a fresh install can configure everything directly:
{
  "listen": "127.0.0.1:7777",
  "reset_grace_seconds": 10,
  "unknown_reset_seconds": 300,
  "response_header_timeout_seconds": 60,
  "max_request_mb": 128,
  "keep_awake_lid_closed": false,
  "keep_awake_lid_closed_power": "ac",
  "primary": {
    "provider": "oauth-passthrough",
    "base_url": "https://api.anthropic.com",
    "failover_strategy": "subscription-limit"
  },
  "secondary": {
    "provider": "bedrock",
    "base_url": "https://bedrock-runtime.us-east-1.amazonaws.com/anthropic",
    "keychain_service": "claude-burst-bedrock",
    "model_map": {
      "claude-sonnet-5": "global.anthropic.claude-sonnet-5",
      "claude-opus-5": "global.anthropic.claude-opus-5"
    }
  },
  "fallback_chain": {
    "claude-fable-5-1": ["claude-opus-5-5"],
    "claude-fable-5": ["claude-opus-5-5"]
  },
  "secondary_pruning": {
    "keep_recent": 10,
    "max_tool_result_bytes": 40960
  },
  "primary_compaction": {
    "enabled": false,
    "warn_at_tokens": 300000,
    "compact_at_tokens": 400000,
    "window_minutes": 60
  },
  "metered_failover": {
    "window_seconds": 60,
    "min_failures": 3
  }
}
primary.provider and secondary.provider can each be oauth-passthrough, anthropic-api-key, openai-compatible or bedrock, and neither slot is tied to a specific vendor. primary.failover_strategy is subscription-limit for the standard setup, where only Anthropic’s own subscription exhaustion headers trigger failover and a bare 429 never does; metered-failures for the no subscription setup, where a sliding window failure count triggers failover instead; subscription-limit+metered-failures for both, so that a genuine Anthropic outage also fails over; or none. Ordinary 4xx errors such as a bad key never count toward the failure window, and neither do failures that are plainly the local machine’s own, such as DNS resolution failing, or a request the client cancelled.
fallback_chain is the ordered list of Claude models to try on the subscription before anything is spent (section 15). secondary_pruning controls the trimming of overflow requests described in section 17, and can be switched off with "disabled": true. primary_compaction is pauseless compaction (section 18), off by default; the thresholds shown are the defaults, and the dashboard’s Pauseless Compaction section can switch it on and adjust them live without a restart. pricing entries, keyed by the model that actually served the request, drive the cost estimates, and a third party model with no entry is reported as unpriced rather than free. Model IDs on Bedrock change over time, so keep model_map aligned with whatever Claude models are actually enabled in your Bedrock account.
25.6 Worked example: Claude Max primary, Together AI and GLM 5.3 as the failover
The secondary does not have to be Bedrock. It can be any OpenAI compatible chat completions endpoint, and Together AI serving GLM 5.3 is the one the project runs and has verified live, including a genuine streaming tool call. This path does real bidirectional translation between Anthropic’s Messages format and OpenAI’s chat completions format, including streaming tool calls and parallel tool call schemas, rather than the byte for byte relay used for Bedrock and the two Anthropic passthrough providers.
Install as usual, then set Together AI as the secondary instead of Bedrock:
./install.sh
claude-burst configure --secondary openai-compatible \
  --secondary-base-url https://api.together.xyz/v1 \
  --secondary-model zai-org/GLM-5.3
TOGETHER_API_KEY='your-together-api-key' claude-burst keychain-set --provider together
claude-burst enable
That leaves the secondary block looking like this, with Claude Max staying primary exactly as before:
"secondary": {
  "provider": "openai-compatible",
  "base_url": "https://api.together.xyz/v1",
  "model": "zai-org/GLM-5.3",
  "keychain_service": "claude-burst-together"
},
"pricing": {
  "zai-org/GLM-5.3": { "input_per_mtok": 1.4, "output_per_mtok": 4.4 }
}
OpenRouter works the same way with https://openrouter.ai/api/v1 as the base URL and OPENROUTER_API_KEY stored with keychain-set --provider openrouter. The routing behaviour is otherwise identical to the Bedrock case: Claude Max serves everything until Anthropic’s own subscription exhaustion headers reject a request, the fallback chain is tried on the subscription, and only then does Claude Burst fail over, translating the request into chat completions format and translating the streamed GLM response back into Anthropic’s event sequence, so Claude Code never has to know the model underneath changed.
Some things do not carry over on this path: images and documents in message content, Anthropic’s extended thinking blocks in history, prompt caching cache_control hints, and Anthropic’s server side tools such as web search are dropped rather than translated, since none have a real equivalent on a generic OpenAI compatible endpoint, and a log line names any server side tool that was dropped. Ordinary coding agent traffic is overwhelmingly text and tool use, so in practice this rarely matters, but it is worth knowing before relying on GLM 5.3 as a burst target for a workload that leans heavily on images or long cached context.
A dual account approach was considered instead of a second vendor entirely: log in as a second, work Claude account and fail over between two Max subscriptions rather than to a different model. It was investigated in enough detail to know how it would have to work, and rejected. Making it work would mean reading and independently refreshing a live Claude Code OAuth credential through an undocumented endpoint, which is exactly the pattern that has gotten other third party tools blocked by Anthropic, and exactly the kind of workaround the earlier sections of this post argue against. Claude Burst treats a rejected request as a real stop, not an obstacle to route around, and that held here too.
25.7 Keeping Remote Control: transparent intercept mode
Claude Code disables Remote Control the moment ANTHROPIC_BASE_URL names anything other than api.anthropic.com, which is a check on the literal value of that variable, not on where the traffic actually ends up. Base URL mode sets exactly that variable, so turning the gateway on that way costs you the feature, and that is why transparent mode is now the recommended mode, with base URL mode as the fallback for anyone who cannot or would rather not touch system files. The code’s own default is still base URL mode, because it is the only mode that needs no privileges and cannot half install; transparent mode is chosen deliberately, from the dashboard or the command line.
Transparent mode gets into the path a level lower than Claude Code’s own settings, at DNS: /etc/hosts points the hostname at the gateway, and the gateway terminates TLS with a locally generated certificate authority trusted only on this one machine. Claude Code believes it reached Anthropic directly, and Remote Control keeps working.
claude-burst configure --intercept-mode transparent
claude-burst enable        # generates the CA, trusts it, prints the one sudo step left
sudo scripts/transparent-root.sh install
sudo scripts/install-pf-heal.sh # arm the redirect guard| transparent (recommended) | base URL (fallback) | |
|---|---|---|
| Remote Control | works | disabled |
| Root required | once, for /etc/hosts and the packet filter | no |
| Certificates | a local CA, trusted only on this machine | none |
| Blast radius | every process on the machine | this user’s Claude Code |
| Guards needed | gateway watchdog and redirect guard | gateway watchdog |
The honest trade is blast radius. While that /etc/hosts entry exists, every process on the machine that talks to that hostname goes through the gateway, so if the gateway is down, Anthropic is unreachable machine wide, not just in one terminal. The install step refuses to run unless the gateway already answers its health check, and verifies the redirect actually works before it ever touches /etc/hosts; removal reverses that ordering. The redirect guard runs as root every thirty seconds and on every network change, probes the real path end to end, reloads the rule if something else on the Mac has removed it, and if four consecutive repairs fail, removes the redirect entirely and says so, because a Mac where Claude Burst is merely out of the path beats one that cannot reach Anthropic at all.
There is one sharp edge worth naming: once /etc/hosts maps that hostname to the gateway, the mapping applies to the gateway’s own outbound requests too, so a naive resolver would have the gateway call itself, forever. It resolves that one intercepted hostname over DNS over HTTPS instead, which never consults /etc/hosts, while leaving the certificate’s expected hostname alone so verification is unchanged.
Undo is one command, safe to run any time and idempotent even if nothing was installed:
sudo scripts/transparent-root.sh removeIf the gateway itself is dead and the dashboard cannot help, the whole recovery chain is committed to the repository and needs nothing installed or built to run. ./scripts/rollback.sh removes the redirect first, then the certificate trust, restores the configuration from the latest backup, stops the gateway, and verifies Anthropic resolves off the machine before claiming success.
25.8 The admin panel, and forcing the secondary on purpose
A subscription primary only fails over on a genuine exhaustion signal, and that cannot be provoked on demand, which means the secondary path can sit completely unexercised for weeks, which is the worst possible moment to discover it is misconfigured. One command routes inference to the secondary on purpose for a window, and another returns to the primary immediately:
claude-burst force-secondary --minutes 15   # inference goes to the secondary
claude-burst reset                          # back to the primary immediately
The forced state is recorded as such, so neither the metrics file nor status ever imply Anthropic reported a limit it did not.
The local control panel runs on 127.0.0.1:7788. It shows the current route, which models are refused and where their traffic is going, usage, the last fifty requests, and the last twenty upstream responses with their headers, since the anthropic-ratelimit-* ones are what actually decide failover. It now also carries the Context and cache panel for overflow pruning, the Pauseless Compaction section with its switch, thresholds, seven day figures and a per session table of context before and after each summary, a Daily activity chart whose Saved view stacks compaction’s tokens not resent with what pruning removed, the Analytics section with spend per repository, the state of both guards, and a Test connection button that proves the live path rather than reading configuration off disk. Anything that needs root or affects the whole machine is not done in process: the button writes a script and opens it in Terminal, where you answer the sudo prompt and watch every command.
It binds loopback only and has no login of its own, which is not automatically the same as safe, since a malicious page can still point a hostname it controls at 127.0.0.1 and try to drive it from your own browser, so every request is checked against the Host header, and every action that changes state requires a header a cross origin request cannot attach without a preflight the server never answers.
25.9 Keeping it running with the lid shut
The lid closed option from section 21 is off by default. To switch it on in the default mode, which stays awake with the lid shut only while plugged in:
claude-burst configure --keep-awake-lid-closed true
sudo scripts/lid-awake-root.sh apply ac      # printed for you if sudo is not cached
Use --keep-awake-power always to stay awake on battery too, with the heat and battery caveats from section 21, and --keep-awake-lid-closed false followed by sudo scripts/lid-awake-root.sh remove to undo it. ./install.sh reapplies whatever config.json says on every run, touching no power settings and asking for no password when the option is off. Check it is live with claude-burst status, which prints a line like this, with any line beneath it starting -> describing drift and the command that fixes it:
keep awake lid closed: on, mode ac (now on AC: SleepDisabled on, Ghostty App Nap disabled on)25.10 Running the tests
go test ./... -race
go vet ./...
Both run automatically on every push and pull request through .github/workflows/test.yml.
25.11 Uninstalling
./install.sh uninstallThis removes the LaunchAgent and the binary, and if the lid closed option was applied it also removes the power source daemon and restores the previous sleep setting, so an uninstall never leaves a Mac that will not sleep. It deliberately leaves metrics, configuration, and the Keychain secret in place, so reinstalling later does not silently wipe your history.
25.12 Where the logs and metrics land
Everything Claude Burst writes goes under ~/.config/claude-burst/, and the log and metrics files are metadata only: prompts, source code, tool inputs, and model outputs are never written to them. metrics.jsonl is one structured line per request, with the route, the actual destination URL, the model requested and the model that served it, HTTP status, latency, token usage including cached tokens, estimated API equivalent cost, and, on a failover, the subscription limit claim and reset timestamp. claude-burst.log is plain text, with a start and done line for every request sharing the same short request id, plus a named stage for anything that failed. Both rotate. The one file that can hold conversation derived content is compaction-state.json, and only when pauseless compaction is switched on, as described in section 14.
Source code
Claude Burst is open source: github.com/andrewbakercloudscale/claude-burst.
The live cost and usage panel referenced in the opening section, the tool that made the original pricing gap visible turn by turn, is also open source: github.com/andrewbakercloudscale/ai-agent-cost-usage-panel.
References
- Anthropic, Plans and Pricing: https://claude.com/pricing
- Anthropic, What is the Max plan?: https://support.claude.com/en/articles/11049741-what-is-the-max-plan
- Anthropic, Use Claude Code with your Pro or Max plan: https://support.claude.com/en/articles/11145838-use-claude-code-with-your-pro-or-max-plan
- Anthropic, Other LLM gateways and subscriptions: https://code.claude.com/docs/en/llm-gateway
- Anthropic, Gateway protocol reference: https://code.claude.com/docs/en/llm-gateway-protocol
- Anthropic, Claude Code error reference: https://code.claude.com/docs/en/errors
- Anthropic, Consumer Terms of Service: https://www.anthropic.com/legal/consumer-terms
- Anthropic, Acceptable Use Policy: https://www.anthropic.com/legal/aup
- Anthropic, Claude Code Legal and Compliance: https://code.claude.com/docs/en/legal-and-compliance
- Anthropic, Claude Code on Amazon Bedrock: https://code.claude.com/docs/en/amazon-bedrock
- AWS, Inference using the Anthropic Messages API: https://docs.aws.amazon.com/bedrock/latest/userguide/inference-messages-api.html
- AWS, Use an Amazon Bedrock API key: https://docs.aws.amazon.com/bedrock/latest/userguide/api-keys-use.html